risingwave is a free, open source databases project written in Rust and released under Apache-2.0. It has 9,330 GitHub stars, 838 forks and 1,687 open issues, and was last pushed 53 minutes ago. On this registry it ranks #85 of 143 tracked projects in Databases, with 5 head-to-head comparisons available.

What is risingwave?

RisingWave is an Apache-2.0, Rust-written event streaming platform for agentic AI that continuously ingests data from databases, event streams and webhooks, processes it incrementally, and serves fresh results at low latency, and it is aimed at teams building agents, real-time applications and streaming data pipelines that need always-current, queryable data.

What it is

RisingWave is an open-source streaming database that unifies ingestion, incremental processing, low-latency serving and durable storage in a single system. It lives in the Infrastructure & Operations / Databases category and speaks the PostgreSQL wire protocol, so it works with psql, JDBC and any Postgres-compatible tooling. Internally it maintains state, tables and materialized views in object storage such as S3, holds query results in an internal row store for serving, and writes long-term data to Apache Iceberg tables through a hosted Iceberg REST catalog.

The concrete problem it solves is the chained real-time stack. The standard approach links Debezium for change data capture, Kafka for transport, Flink for processing and a database for serving, and every hop in that chain adds latency and operational overhead. RisingWave replaces the whole stack — ingest, process, serve, store — with one system whose results are recomputed incrementally, meaning only the affected results are recalculated when upstream data changes.

Key capabilities

  • Ingests across the full data spectrum: HTTP webhooks, native CDC from PostgreSQL and MySQL via transaction log reading, event streams from Kafka, Pulsar and Kinesis, and batch data from S3 and data warehouses, all under one SQL interface where streams and tables join freely.
  • Performs incremental computation over materialized views with end-to-end freshness under 100 ms, without full recomputation on every query.
  • Serves results from an internal row store at 10–20 ms p99 latency, queried directly with standard SQL — no polling, cache warming or TTL management.
  • Writes to Apache Iceberg tables, hosting the Iceberg REST catalog itself and handling compaction, small-file optimization and snapshot cleanup without external tooling.
  • Executes Iceberg queries through Apache DataFusion, a vectorized query engine, keeping data readable by Spark, Trino and DuckDB because Iceberg is an open format.
  • Provides an MCP server, a CLI and Skills so agents can query and operate RisingWave without custom integration.
  • Stores internal state in object storage roughly 100x cheaper than RAM, with an elastic disk cache that pins hot data on local SSD or EBS for latency-sensitive workloads.

Who uses it and how

  • Agentic AI applications query the serving layer directly with SQL, and operate the system through the MCP server, CLI and Skills rather than bespoke integration code.
  • Monitoring and alerting pipelines continuously evaluate streaming metrics against thresholds.
  • Feature stores compute batch and streaming features over the same pipeline and serve them from the same system.
  • Live dashboards run on incrementally updated materialized views, with no scheduled refreshes.
  • Streaming lakehouse workloads ingest continuously and exactly once into open-format tables with automated compaction and snapshot management.

Getting started

The fastest path runs curl -L https://risingwave.com/sh | sh, which installs and starts the system in about 60 seconds. Docker, Kubernetes and other options are documented in the quick start guide.

How it compares

The tools it consolidates are Debezium, Kafka, Flink and a serving database, so the comparison is less about licence than about count: RisingWave is one Apache-2.0 system where that stack is four, and the open Iceberg layer keeps data readable by Spark, Trino and DuckDB rather than trapped in a proprietary store. Teams already standardized on managed brokers and stream processors should weigh that consolidation against existing operational knowledge.

When to use it — and when not to

A self-hoster must run object storage such as S3 or an equivalent for state and tables, and for latency-sensitive work should add local SSD or EBS for the disk cache; there is no separate catalog service to operate because the Iceberg REST catalog is hosted internally. It is a poor fit for teams that need only periodic batch analytics, or that are unwilling to adopt a new streaming engine in place of an existing Kafka and Flink investment. The repository carries a substantial open-issue count of 1687, which is worth reviewing before committing to it as the single system behind production serving.

project readme (upstream, from github) — read inline

🌊 Event Streaming for Agentic AI

Docs | Benchmarks | Demos | Case Studies

<a href="https://github.com/risingwavelabs/risingwave/releases/latest" target="_blank"

Release Slack X YouTube

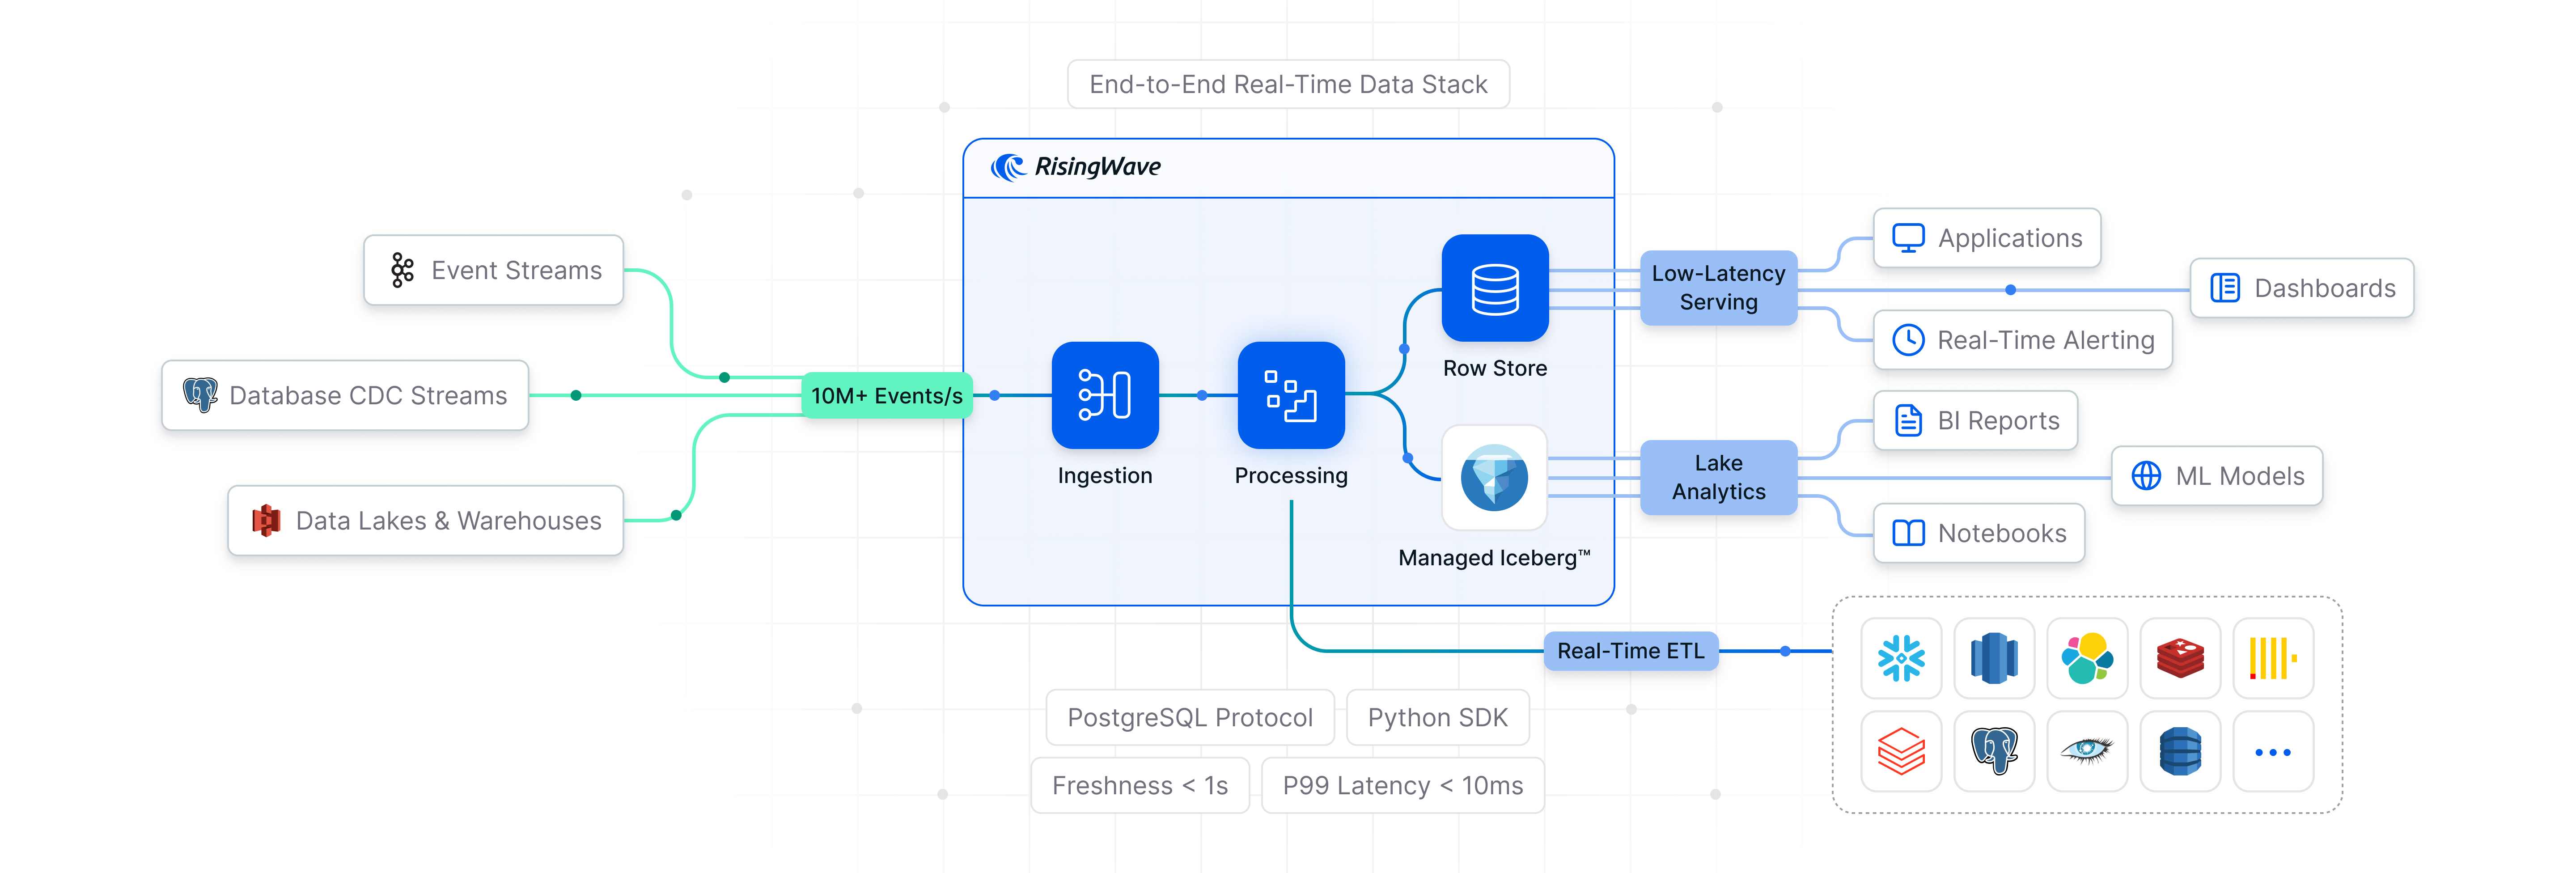
RisingWave is an event streaming platform for agentic AI. It continuously ingests data from databases, event streams, and webhooks, processes it incrementally, and serves fresh results at low latency, replacing the traditional event streaming stack (e.g., Debezium + Kafka + Flink + serving DB) with a single system.
RisingWave


Try it out in 60 seconds

curl -L https://risingwave.com/sh | sh

For Docker, Kubernetes, and other options, see the quick start guide.


The problem

Agents and real-time applications need data that is always fresh and queryable at low latency. The standard approach chains together Debezium for CDC, Kafka for transport, Flink for processing, and a database for serving. Each hop adds latency and each system adds operational overhead.

RisingWave replaces the whole stack: ingest, process, serve, store.


How it works

Ingest from any source

RisingWave ingests across the full data spectrum:

  • Webhooks: HTTP-based event ingestion from SaaS applications and external systems
  • Database changes: native CDC from PostgreSQL, MySQL, and others via transaction log reading
  • Event streams: Kafka, Pulsar, Kinesis, and other message brokers
  • Historical data: batch ingestion from S3, data warehouses, and other storage systems

All sources are unified under the same SQL interface. Streams and tables can be joined freely.

Process continuously

RisingWave performs incremental computation over ingested data. When upstream data changes, only the affected results are recomputed. End-to-end freshness is under 100 ms.

This is the core mechanism behind everything RisingWave does: materialized views that are always up to date, without full recomputation on every query.

Serve at low latency

Query results are maintained in RisingWave's internal row store and served at 10-20 ms p99 latency. Agents and applications query this layer directly using standard SQL. No polling, no cache warming, no TTL management.

Store in Apache Iceberg™

For long-term retention and analytical access, RisingWave writes to Apache Iceberg™ tables. It hosts the Iceberg REST catalog directly and handles table maintenance — compaction, small-file optimization, snapshot cleanup — without external tooling. Iceberg queries are executed via Apache DataFusion, a vectorized query engine. Because Iceberg is an open format, data is also readable by Spark, Trino, DuckDB, and other engines.

The row store and Iceberg layer serve different purposes: the row store is for low-latency serving, Iceberg is for durable, open-format storage and analytical queries. RisingWave manages both.


Use cases

  • Monitoring and alerting: continuous evaluation of streaming metrics against thresholds
  • Feature stores: batch and streaming features computed over the same pipeline, served from the same system
  • Live dashboards: materialized views updated incrementally, no scheduled refreshes
  • Real-time enrichment: live events joined with historical reference data in-flight, before delivery downstream
  • Streaming lakehouses: continuous, exactly-once ingestion into open-format tables with automated compaction and snapshot management

Design decisions

Ultimate cost efficiency

Internal state, tables, and materialized views are stored in object storage (S3 or equivalent), which is roughly 100x cheaper than RAM. This enables elastic scaling without data rebalancing and failure recovery in seconds. For latency-sensitive workloads, elastic disk cache pins hot data on local SSD or EBS, keeping p99 query latency at 10-20 ms.

Native experience for both humans and agents

RisingWave connects via the PostgreSQL wire protocol and works with psql, JDBC, and any Postgres-compatible tooling. For agents, RisingWave provides a MCP server, a CLI, and Skills, so agents can query and operate RisingWave without custom integration.

Openness

RisingWave natively integrates with Apache Iceberg™ for continuous stream ingestion, direct reads via DataFusion, and automated table maintenance. Data in Iceberg is in an open format and accessible to any compatible query engine.


Deployment

RisingWave Cloud is the managed option.

For self-hosted:


Community

Join us on Slack for questions, discussions, and contributions.


Telemetry

RisingWave uses Scarf for anonymized installation analytics and collects anonymous usage statistics to improve the product. Both can be opted out. See the telemetry documentation for details.


License

Apache License 2.0. See LICENSE.

Contributing

See the RisingWave Developer Guide.

Frequently asked questions

Is risingwave free to use?

risingwave is open source under the Apache-2.0 licence. There is no licence fee and no seat count — you can self-host it or, where the project offers one, pay a vendor for a managed version instead.

What does risingwave do?

Event streaming platform for agentic AI. Continuously ingest, transform, and serve event streams in real time, at scale.

What is risingwave written in?

risingwave is primarily written in Rust. Its source is publicly available at https://github.com/risingwavelabs/risingwave, and it has 9,330 GitHub stars.