Reader
Open source web infrastructure for AI.
Access the web without the complexity.


The Problem
Building agents that need web access is frustrating. You piece together Puppeteer, add stealth plugins, fight Cloudflare, manage proxies and it still breaks in production.
Because production grade web scraping isn't about rendering a page and converting HTML to markdown. It's about everything underneath:
| Layer | What it actually takes |
|---|---|
| Browser architecture | Managing browser instances at scale, not one-off scripts |
| Anti-bot bypass | Cloudflare, Turnstile, JS challenges, they all block naive scrapers |
| TLS fingerprinting | Real browsers have fingerprints. Puppeteer doesn't. Sites know. |
| Proxy infrastructure | Standard vs premium, rotation strategies, sticky sessions |
| Resource management | Browser pooling, memory limits, graceful recycling |
| Reliability | Rate limiting, retries, timeouts, caching, graceful degradation |
I built Reader, a production-grade web scraping engine on top of Playwright, with stealth and anti-detection built in from the ground up.
The Solution
Three primitives. That's it.
import { ReaderClient } from "@vakra-dev/reader";
import { chromium } from "playwright-core";

const reader = new ReaderClient();

// 1. Scrape URLs → clean markdown
const result = await reader.scrape({ urls: ["https://example.com"] });
console.log(result.data[0].markdown);

// 2. Crawl a site → discover + scrape pages
const pages = await reader.crawl({
  url: "https://example.com",
  depth: 2,
  scrape: true,
});
console.log(`Found ${pages.urls.length} pages`);

// 3. Browser session → full Playwright/Puppeteer control with stealth
const session = await reader.browser();
const browser = await chromium.connectOverCDP(session.wsEndpoint);
const page = browser.contexts()[0].pages()[0];
await page.goto("https://example.com");
console.log(await page.title());
await session.close();
All the hard stuff (browser pooling, anti-bot bypass, proxy rotation, retries) happens under the hood. You get clean markdown. Your agents get the web. And when you need full browser control, browser() gives you a stealthed Chrome that Playwright or Puppeteer can drive.
[!TIP] If Reader is useful to you, a star on GitHub helps others discover the project.
Features
- Browser Sessions - Launch stealthed Chrome, connect Playwright/Puppeteer via CDP
- Anti-Bot Bypass - TLS fingerprinting, navigator spoofing, WebRTC masking,
webdriver=false - Clean Output - Markdown and HTML with automatic main content extraction
- Smart Content Cleaning - Removes nav, headers, footers, popups, cookie banners
- CLI & API - Use from command line or programmatically
- Browser Pool - Auto-recycling, health monitoring, tiered proxy pools
- Concurrent Scraping - Parallel URL processing with progress tracking
- Website Crawling - BFS link discovery with depth/page limits
- Tiered Proxies - Standard and premium proxy pools with health tracking
Installation
npm install @vakra-dev/reader
Requirements: Node.js >= 18
First run: Playwright bundles Chromium for all platforms. Install it with:
npx playwright install chromium
Quick Start
Cloud (Fastest)
Get an API key at console.reader.dev and start scraping immediately:
import { ReaderClient } from "@vakra-dev/reader-js";

const reader = new ReaderClient({ apiKey: process.env.READER_API_KEY });

const result = await reader.read({ url: "https://example.com" });
if (result.kind === "scrape") {
  console.log(result.data.markdown);
}
npm install @vakra-dev/reader-js
See the cloud docs for the full API reference.
Self-Hosted
Install the reader engine and run scraping on your own infrastructure:
Basic Scrape
import { ReaderClient } from "@vakra-dev/reader";

const reader = new ReaderClient();

const result = await reader.scrape({
  urls: ["https://example.com"],
  formats: ["markdown", "html"],
});

console.log(result.data[0].markdown);
console.log(result.data[0].html);

await reader.close();
Batch Scraping with Concurrency
import { ReaderClient } from "@vakra-dev/reader";

const reader = new ReaderClient();

const result = await reader.scrape({
  urls: ["https://example.com", "https://example.org", "https://example.net"],
  formats: ["markdown"],
  batchConcurrency: 3,
  onProgress: (progress) => {
    console.log(`${progress.completed}/${progress.total}: ${progress.currentUrl}`);
  },
});

console.log(`Scraped ${result.batchMetadata.successfulUrls} URLs`);

await reader.close();
Crawling
import { ReaderClient } from "@vakra-dev/reader";

const reader = new ReaderClient();

const result = await reader.crawl({
  url: "https://example.com",
  depth: 2,
  maxPages: 20,
  scrape: true,
});

console.log(`Discovered ${result.urls.length} URLs`);
console.log(`Scraped ${result.scraped?.batchMetadata.successfulUrls} pages`);

await reader.close();
Browser Session
Launch a stealthed Chrome and control it with Playwright or Puppeteer. The browser has anti-bot stealth active (webdriver=false, navigator spoofing, WebRTC masking). Your existing scripts just work.
import { ReaderClient } from "@vakra-dev/reader";
import { chromium } from "playwright-core";

const reader = new ReaderClient();

// Create a browser session - returns a CDP WebSocket URL
const session = await reader.browser();

// Connect Playwright (one-line change from a local script)
const browser = await chromium.connectOverCDP(session.wsEndpoint);
const context = await browser.newContext();
const page = await context.newPage();

// Use Playwright normally - full stealth active
await page.goto("https://news.ycombinator.com/");
console.log(await page.title());

await browser.close();
await session.close();
await reader.close();
Also works with Puppeteer:
import { connect } from "puppeteer-core";

const browser = await connect({ browserWSEndpoint: session.wsEndpoint });
With Proxy
import { ReaderClient } from "@vakra-dev/reader";

const reader = new ReaderClient();

const result = await reader.scrape({
  urls: ["https://example.com"],
  formats: ["markdown"],
  proxy: {
    type: "premium",
    host: "proxy.example.com",
    port: 8080,
    username: "username",
    password: "password",
    country: "us",
  },
});

await reader.close();
With Tiered Proxy Pools
Configure standard (datacenter, fast) and premium (residential, anti-bot) proxy tiers:
import { ReaderClient } from "@vakra-dev/reader";

const reader = new ReaderClient({
  proxyPools: {
    standard: [
      { url: "http://user:pass@dc-proxy1:8080" },
      { url: "http://user:pass@dc-proxy2:8080" },
    ],
    premium: [{ url: "http://user:pass@res-proxy1:8080" }],
  },
});

const result = await reader.scrape({
  urls: ["https://example.com"],
  proxyMode: "standard", // or "premium" for anti-bot sites
});

await reader.close();
Or via environment variables:
PROXY_STANDARD=http://user:pass@dc1:8080,http://user:pass@dc2:8080
PROXY_PREMIUM=http://user:pass@res1:8080
With Browser Pool Configuration
import { ReaderClient } from "@vakra-dev/reader";

const reader = new ReaderClient({
  browserPool: {
    size: 5, // 5 browser instances
    retireAfterPages: 50, // Recycle after 50 pages
    retireAfterMinutes: 15, // Recycle after 15 minutes
  },
  verbose: true,
});

const result = await reader.scrape({
  urls: manyUrls,
  batchConcurrency: 5,
});

await reader.close();
CLI Reference
Daemon Mode
For multiple requests, start a daemon to keep browser pool warm:
# Start daemon with browser pool
npx reader start --direct-pool-size 5

# All subsequent commands auto-connect to daemon
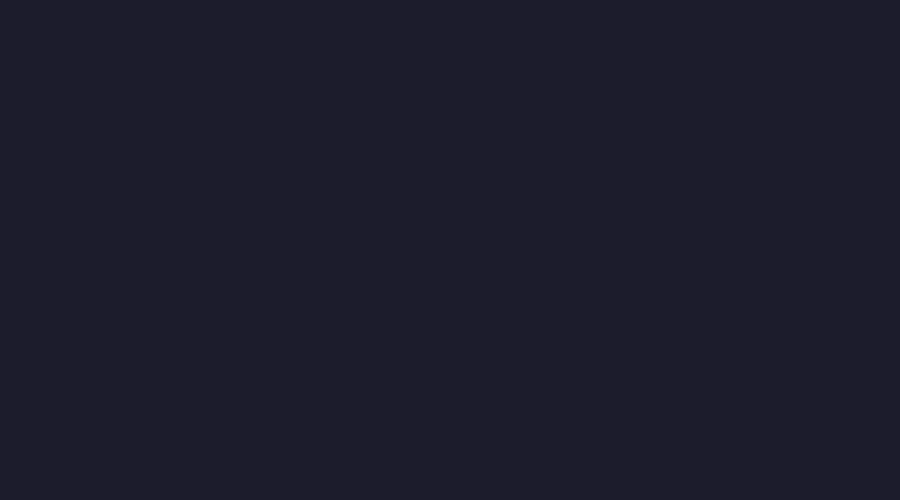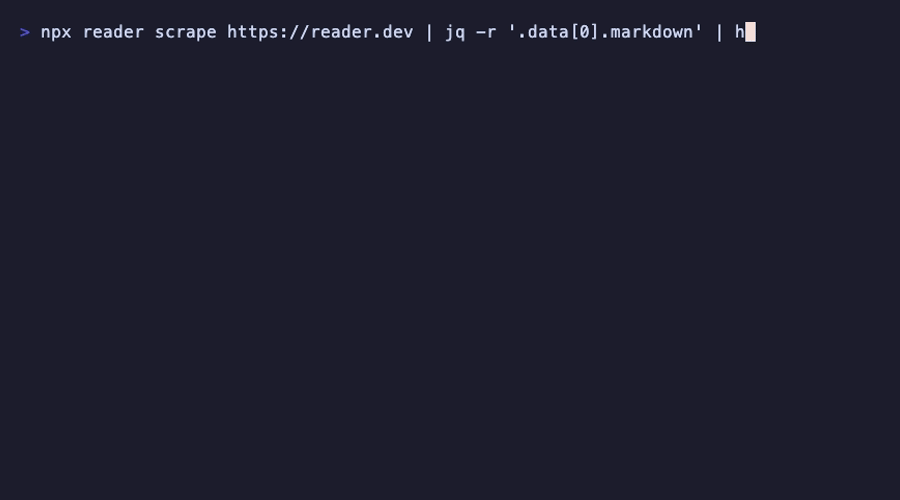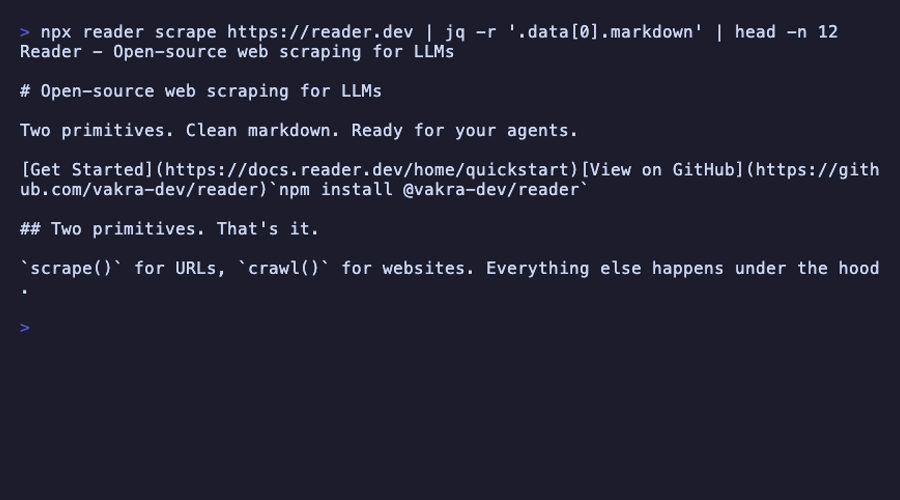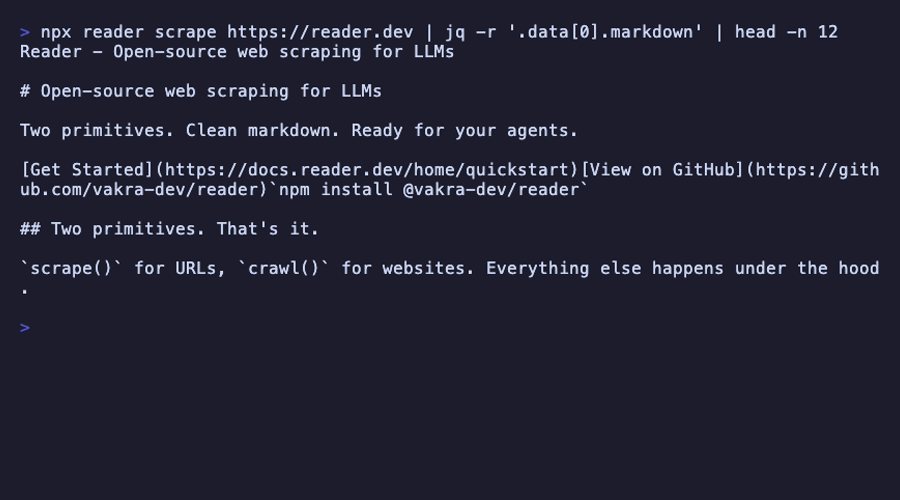
npx reader scrape https://example.com
npx reader crawl https://example.com -d 2

# Check daemon status
npx reader status

# Stop daemon
npx reader stop

# Force standalone mode (bypass daemon)
npx reader scrape https://example.com --standalone
reader scrape
Scrape one or more URLs.
# Scrape a single URL
npx reader scrape https://example.com

# Scrape with multiple formats
npx reader scrape https://example.com -f markdown,html

# Scrape multiple URLs concurrently
npx reader scrape https://example.com https://example.org -c 2

# Save to file
npx reader scrape https://example.com -o output.md
| Option | Type | Default | Description |
|---|---|---|---|
-f, --format |
string | "markdown" |
Output formats (comma-separated: markdown,html) |
-o, --output |
string | stdout | Output file path |
-c, --concurrency |
number | 1 |
Parallel requests |
-t, --timeout |
number | 30000 |
Request timeout in milliseconds |
--batch-timeout |
number | 300000 |
Total timeout for entire batch operation |
--proxy |
string | - | Proxy URL (e.g., http://user:pass@host:port) |
--user-agent |
string | - | Custom user agent string |
--show-chrome |
flag | - | Show browser window for debugging |
--no-main-content |
flag | - | Disable main content extraction (include full page) |
--include-tags |
string | - | CSS selectors for elements to include (comma-separated) |
--exclude-tags |
string | - | CSS selectors for elements to exclude (comma-separated) |
-v, --verbose |
flag | - | Enable verbose logging |
reader crawl
Crawl a website to discover pages.
# Crawl with default settings
npx reader crawl https://example.com

# Crawl deeper with more pages
npx reader crawl https://example.com -d 3 -m 50

# Crawl and scrape content
npx reader crawl https://example.com -d 2 --scrape

# Filter URLs with patterns
npx reader crawl https://example.com --include "blog/*" --exclude "admin/*"
| Option | Type | Default | Description |
|---|---|---|---|
-d, --depth |
number | 1 |
Maximum crawl depth |
-m, --max-pages |
number | 20 |
Maximum pages to discover |
-s, --scrape |
flag | - | Also scrape content of discovered pages |
-f, --format |
string | "markdown" |
Output formats when scraping (comma-separated) |
-o, --output |
string | stdout | Output file path |
--delay |
number | 1000 |
Delay between requests in milliseconds |
-t, --timeout |
number | - | Total timeout for crawl operation |
--include |
string | - | URL patterns to include (comma-separated regex) |
--exclude |
string | - | URL patterns to exclude (comma-separated regex) |
--proxy |
string | - | Proxy URL (e.g., http://user:pass@host:port) |
--user-agent |
string | - | Custom user agent string |
--show-chrome |
flag | - | Show browser window for debugging |
-v, --verbose |
flag | - | Enable verbose logging |
reader browser
Launch a browser session with a CDP WebSocket endpoint.
# Create a session (prints wsEndpoint, blocks until Ctrl+C)
npx reader browser create

# Create with options
npx reader browser create --timeout 60000 --show-chrome

# List active sessions (daemon mode)
npx reader browser list

# Stop a session
npx reader browser stop <sessionId>
| Option | Type | Default | Description |
|---|---|---|---|
--proxy |
string | - | Proxy URL |
-t, --timeout |
number | 300000 |
Session lifetime in milliseconds |
--show-chrome |
flag | - | Show browser window |
--standalone |
flag | - | Force standalone mode |
-v, --verbose |
flag | - | Enable verbose logging |
API Reference
ReaderClient
The recommended way to use Reader. Manages the Playwright browser pool lifecycle automatically.
import { ReaderClient } from "@vakra-dev/reader";

const reader = new ReaderClient({ verbose: true });

// Scrape
const result = await reader.scrape({ urls: ["https://example.com"] });

// Crawl
const crawlResult = await reader.crawl({ url: "https://example.com", depth: 2 });

// Browser session
const session = await reader.browser();
// → session.wsEndpoint for Playwright/Puppeteer

// Close when done (optional - auto-closes on exit)
await reader.close();
Constructor Options
| Option | Type | Default | Description |
|---|---|---|---|
verbose |
boolean |
false |
Enable verbose logging |
showChrome |
boolean |
false |
Show browser window for debugging |
browserPool |
BrowserPoolConfig |
undefined |
Browser pool configuration (size, recycling) |
proxyPools |
ProxyPoolConfig |
undefined |
Tiered proxy pools (standard + premium) |
proxies |
ProxyConfig[] |
undefined |
Array of proxies for rotation (legacy) |
proxyRotation |
string |
"round-robin" |
Rotation strategy: "round-robin" or "random" |
BrowserPoolConfig
| Option | Type | Default | Description |
|---|---|---|---|
size |
number |
2 |
Number of browser instances in pool |
retireAfterPages |
number |
100 |
Recycle browser after N page loads |
retireAfterMinutes |
number |
30 |
Recycle browser after N minutes |
maxQueueSize |
number |
100 |
Max pending requests in queue |
Methods
| Method | Description |
|---|---|
scrape(options) |
Scrape one or more URLs |
crawl(options) |
Crawl a website to discover pages |
browser(options?) |
Launch a stealthed browser session (CDP WebSocket) |
start() |
Pre-initialize browser pool (optional) |
isReady() |
Check if client is initialized |
close() |
Close client and release resources |
scrape(options): Promise
Scrape one or more URLs. Can be used directly or via ReaderClient.
| Option | Type | Required | Default | Description |
|---|---|---|---|---|
urls |
string[] |
Yes | - | Array of URLs to scrape |
formats |
Array |
No | ["markdown"] |
Output formats |
onlyMainContent |
boolean |
No | true |
Extract only main content (removes nav/header/footer) |
includeTags |
string[] |
No | [] |
CSS selectors for elements to keep |
excludeTags |
string[] |
No | [] |
CSS selectors for elements to remove |
waitForSelector |
string |
No | - | CSS selector to wait for before page is loaded |
timeoutMs |
number |
No | 30000 |
Request timeout in milliseconds |
batchConcurrency |
number |
No | 1 |
Number of URLs to process in parallel |
batchTimeoutMs |
number |
No | 300000 |
Total timeout for entire batch operation |
proxy |
ProxyConfig |
No | - | Proxy configuration object |
proxyTier |
ProxyTier |
No | - | Proxy tier: "standard" or "premium" |
onProgress |
function |
No | - | Progress callback: ({ completed, total, currentUrl }) => void |
verbose |
boolean |
No | false |
Enable verbose logging |
showChrome |
boolean |
No | false |
Show Chrome window for debugging |
Returns: Promise
interface ScrapeResult {
  data: WebsiteScrapeResult[];
  batchMetadata: BatchMetadata;
}

interface WebsiteScrapeResult {
  markdown?: string;
  html?: string;
  metadata: {
    baseUrl: string;
    finalUrl?: string; // Present if URL redirected
    totalPages: number;
    scrapedAt: string;
    duration: number;
    website: WebsiteMetadata;
  };
}

interface BatchMetadata {
  totalUrls: number;
  successfulUrls: number;
  failedUrls: number;
  scrapedAt: string;
  totalDuration: number;
  errors?: Array<{ url: string; error: string }>;
}
crawl(options): Promise
Crawl a website to discover pages.
| Option | Type | Required | Default | Description |
|---|---|---|---|---|
url |
string |
Yes | - | Single seed URL to start crawling from |
depth |
number |
No | 1 |
Maximum depth to crawl |
maxPages |
number |
No | 20 |
Maximum pages to discover |
scrape |
boolean |
No | false |
Also scrape full content of discovered pages |
delayMs |
number |
No | 1000 |
Delay between requests in milliseconds |
timeoutMs |
number |
No | - | Total timeout for entire crawl operation |
includePatterns |
string[] |
No | - | URL patterns to include (regex strings) |
excludePatterns |
string[] |
No | - | URL patterns to exclude (regex strings) |
formats |
Array |
No | ["markdown"] |
Output formats for scraped content |
scrapeConcurrency |
number |
No | 2 |
Number of URLs to scrape in parallel |
proxy |
ProxyConfig |
No | - | Proxy configuration object |
userAgent |
string |
No | - | Custom user agent string |
verbose |
boolean |
No | false |
Enable verbose logging |
showChrome |
boolean |
No | false |
Show Chrome window for debugging |
Returns: Promise
interface CrawlResult {
  urls: CrawlUrl[];
  scraped?: ScrapeResult;
  metadata: CrawlMetadata;
}

interface CrawlUrl {
  url: string;
  title: string;
  description: string | null;
}

interface CrawlMetadata {
  totalUrls: number;
  maxDepth: number;
  totalDuration: number;
  seedUrl: string;
}
browser(options?): Promise
Launch a stealthed Chrome and return a CDP WebSocket URL for Playwright/Puppeteer.
| Option | Type | Required | Default | Description |
|---|---|---|---|---|
proxy |
ProxyConfig |
No | - | Proxy configuration |
proxyTier |
ProxyTier |
No | - | Proxy tier: "standard" or "premium" |
showChrome |
boolean |
No | false |
Show browser window |
timeoutMs |
number |
No | 300000 |
Session lifetime (auto-closes after) |
verbose |
boolean |
No | false |
Enable verbose logging |
Returns: Promise
interface BrowserSession {
  sessionId: string; // Unique session identifier
  wsEndpoint: string; // CDP WebSocket URL for Playwright/Puppeteer
  createdAt: string; // ISO timestamp
  close(): Promise<void>; // Close session and release resources
}
Stealth features active on all sessions:
navigator.webdriver = false(via--disable-blink-features=AutomationControlled)- Proxy routing through authenticated proxy forwarder (if configured)
- Isolated user profile per session (no cookie/state leaks)
ProxyConfig
| Option | Type | Required | Default | Description |
|---|---|---|---|---|
url |
string |
No | - | Full proxy URL (takes precedence over other fields) |
type |
"standard" | "premium" |
No | - | Proxy type |
host |
string |
No | - | Proxy host |
port |
number |
No | - | Proxy port |
username |
string |
No | - | Proxy username |
password |
string |
No | - | Proxy password |
country |
string |
No | - | Country code for residential proxies (e.g., 'us', 'uk') |
Daemon Mode (Production)
For production servers, start the daemon once and all scrape/crawl/browser requests share the warm browser pool:
import { ReaderClient } from "@vakra-dev/reader";

// Create once at startup
const reader = new ReaderClient({
  proxyPools: {
    standard: [{ url: "http://user:pass@dc-proxy:8080" }],
    premium: [{ url: "http://user:pass@res-proxy:8080" }],
  },
});

// Reuse for all requests
const result = await reader.scrape({ urls: ["https://example.com"] });

// Graceful shutdown
process.on("SIGTERM", () => reader.close());
How It Works
Anti-Bot Bypass
Reader uses Playwright with stealth enhancements for advanced anti-detection:
- Fingerprint Generation - Randomized browser fingerprints via fingerprint-generator
- Navigator Spoofing -
webdriver=false, device memory, hardware concurrency - Stealth Scripts - Injected scripts that patch automation indicators
- WebRTC IP Masking - Prevents IP leaks through WebRTC connections
- Proxy Chaining - Traffic routed through proxy-chain for IP management
Browser Pool
- Tiered Proxy Pools - Separate standard and premium proxy pools
- Auto-Recycling - Browsers recycled after 100 requests or 30 minutes
- Health Tracking - Auto-benches failed proxies for 5 minutes, revives on recovery
- Per-Proxy Concurrency - Limits concurrent requests per proxy URL (default: 2)
HTML to Markdown: supermarkdown
Reader uses supermarkdown for HTML to Markdown conversion - a sister project we built from scratch specifically for web scraping and LLM pipelines.
Why we built it:
When you're scraping the web, you encounter messy, malformed HTML that breaks most converters. And when you're feeding content to LLMs, you need clean output without artifacts or noise. We needed a converter that handles real-world HTML reliably while producing high-quality markdown.
What supermarkdown offers:
| Feature | Benefit |
|---|---|
| Written in Rust | Native performance with Node.js bindings via napi-rs |
| Full GFM support | Tables, task lists, strikethrough, autolinks |
| LLM-optimized | Clean output designed for AI consumption |
| Battle-tested | Handles malformed HTML from real web pages |
| CSS selectors | Include/exclude elements during conversion |
supermarkdown is open source and available as both a Rust crate and npm package:
# npm
npm install @vakra-dev/supermarkdown

# Rust
cargo add supermarkdown
Check out the supermarkdown repository for examples and documentation.
Server Deployment
Reader uses a real Chromium browser under the hood. On headless Linux servers (VPS, EC2, etc.), you need to install Chrome's system dependencies:
# Debian/Ubuntu
sudo apt-get install -y libnspr4 libnss3 libatk1.0-0 libatk-bridge2.0-0 \
  libcups2 libxcb1 libatspi2.0-0 libx11-6 libxcomposite1 libxdamage1 \
  libxext6 libxfixes3 libxrandr2 libgbm1 libcairo2 libpango-1.0-0 libasound2
This is the same requirement that Puppeteer and Playwright have on headless Linux. macOS, Windows, and Linux desktops already have these libraries.
For Docker and production deployment guides, see the deployment documentation.
Documentation
Full documentation is available at docs.reader.dev, including guides for scraping, crawling, proxy configuration, browser pool management, and deployment.
Examples
| Example | Description |
|---|---|
| Basic Scraping | Simple single-URL scraping |
| Batch Scraping | Concurrent multi-URL scraping |
| Crawl Website | Crawl and discover pages |
| Browser Session (Playwright) | Navigate, extract data, screenshot |
| Browser Session (Actions) | Click, type, search, wait for elements |
| Browser Session (Puppeteer) | Puppeteer via connect({ browserWSEndpoint }) |
| Browser Session (Raw CDP) | Direct CDP WebSocket commands |
| Browser Pool Config | Configure browser pool for high throughput |
| Proxy Pool | Proxy rotation with multiple proxies |
| Cloudflare Bypass | Scrape Cloudflare-protected sites |
| All Formats | Output in markdown and html |
| AI Tools | OpenAI, Anthropic, LangChain integrations |
Development
# Install dependencies
npm install

# Run linting
npm run lint

# Format code
npm run format

# Type check
npm run typecheck

# Find TODOs
npm run todo
Contributing
Contributions welcome! Please see CONTRIBUTING.md for guidelines.
License
Apache 2.0 - See LICENSE for details.
Citation
If you use Reader in your research or project, please cite it:
@software{reader.dev,
  author = {Kaul, Nihal},
  title = {Reader: Open-source, production-grade web scraping engine built for LLMs},
  year = {2026},
  publisher = {GitHub},
  url = {https://github.com/vakra-dev/reader}
}