Frustratingly simple ETL for Postgres


PeerDB
At PeerDB, we are building a fast, simple and the most cost effective way to stream data from Postgres to Data Warehouses, Queues and Storage engines. If you are running Postgres at the heart of your data-stack and move data at scale from Postgres to any of the above targets, PeerDB can provide value.
We support different modes of streaming - log based (CDC), cursor based (timestamp or integer) and XMIN based. Performance wise, we are 10x faster than existing tools. Features wise, we support native Postgres features such as comprehensive set of data-types incl. jsonb/arrays/geospatial, efficiently streaming TOAST columns, schema changes and so on.
Mirror type deprecation notice: CDC is the recommended and actively-maintained mirror type. The Query Replication (QRep) and XMIN mirror types are deprecated and no longer actively maintained; they remain fully functional, and no code is currently being removed.
Connector deprecation notice: The Snowflake, BigQuery, ElasticSearch, Kafka (including Confluent and Redpanda variants), Azure Event Hubs, Google Pub/Sub, and S3 destination connectors are deprecated and no longer actively maintained. They remain fully functional in the current and all prior releases, and no code is currently being removed. The actively-maintained paths going forward are Postgres → ClickHouse, Postgres → ClickHouse Cloud, and Postgres → Postgres. This deprecation applies to the destination role only — BigQuery remains a supported source. See the connector status matrix and the deprecated connectors migration guide for how to pin to a release or fork the relevant code.
Get started
git clone [email protected]:PeerDB-io/peerdb.git
cd peerdb

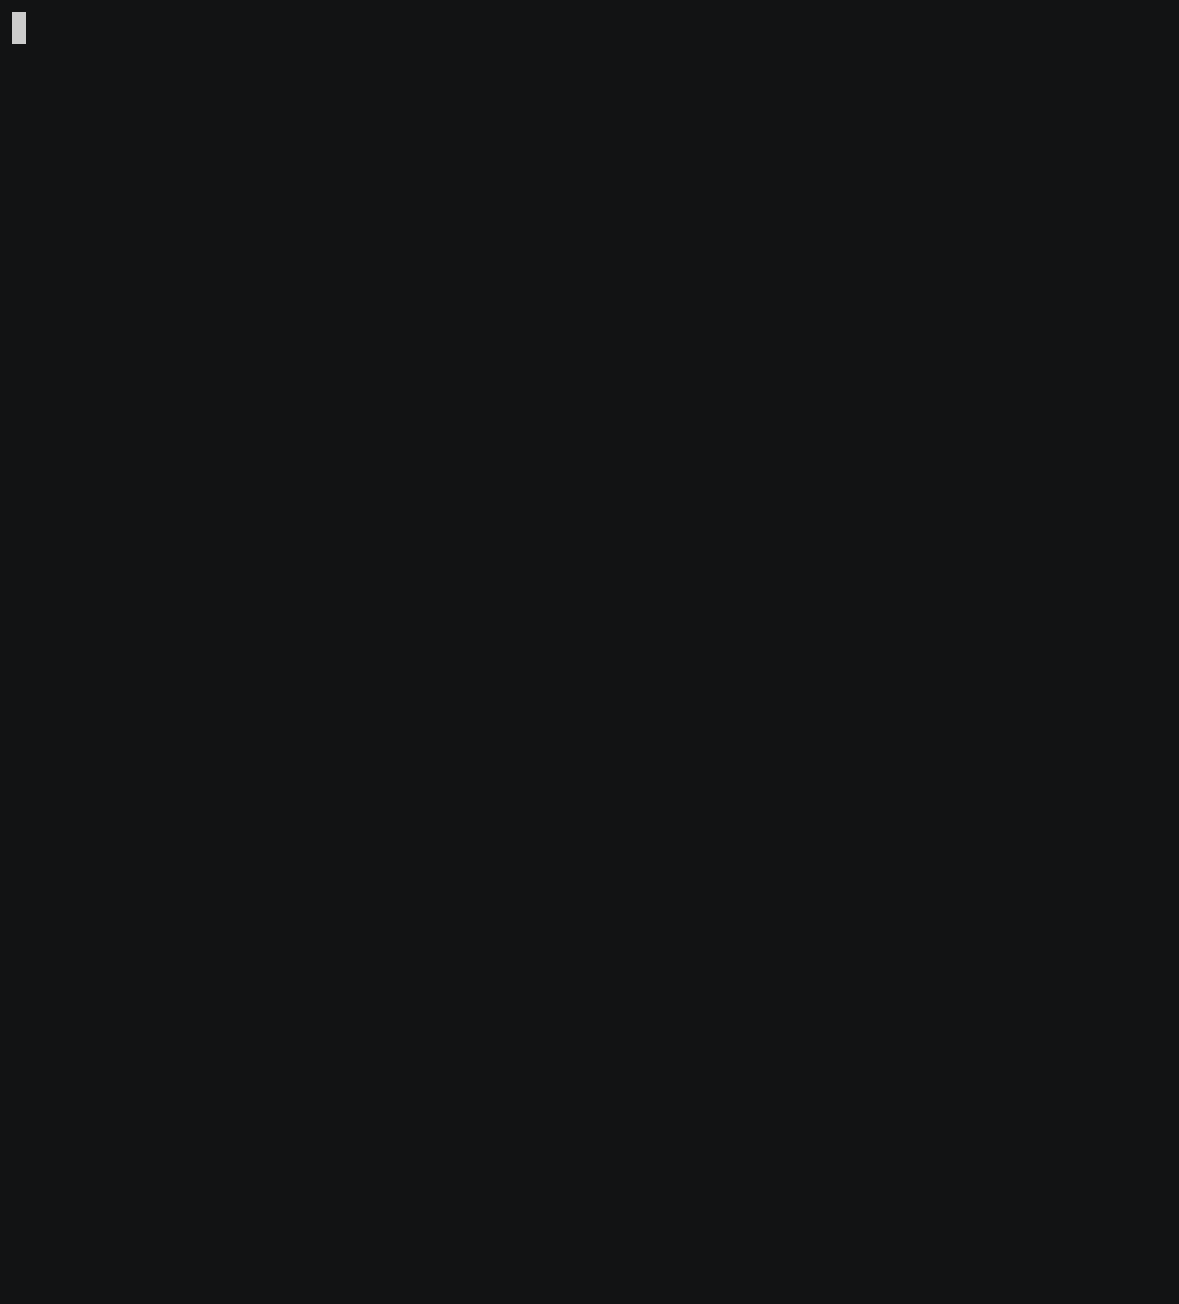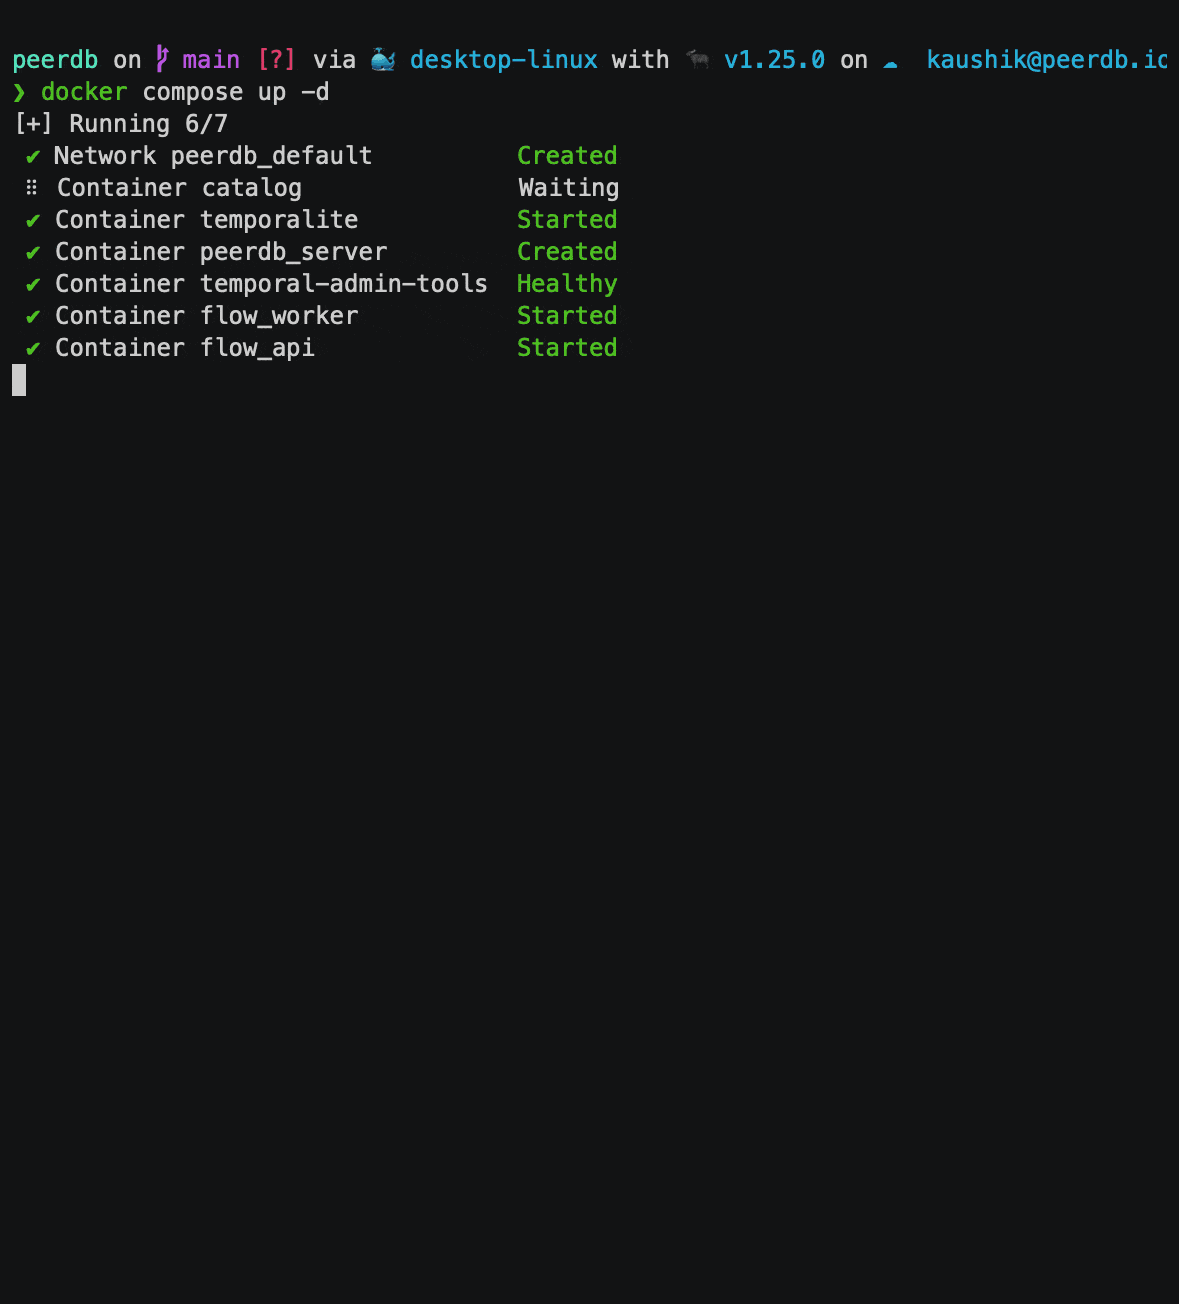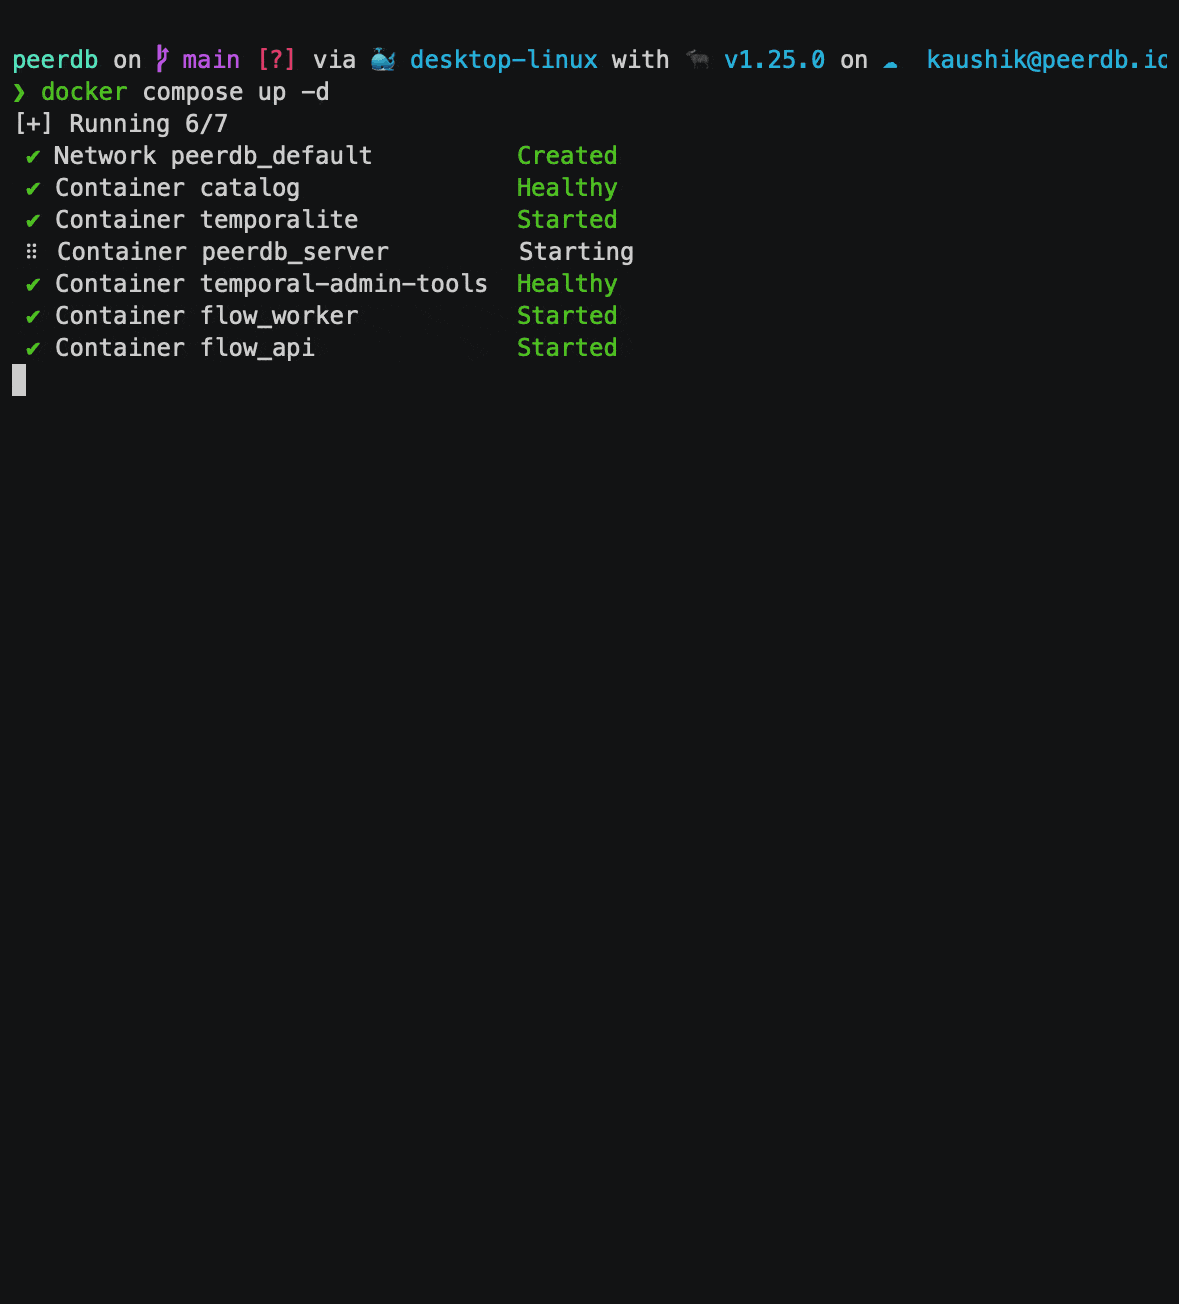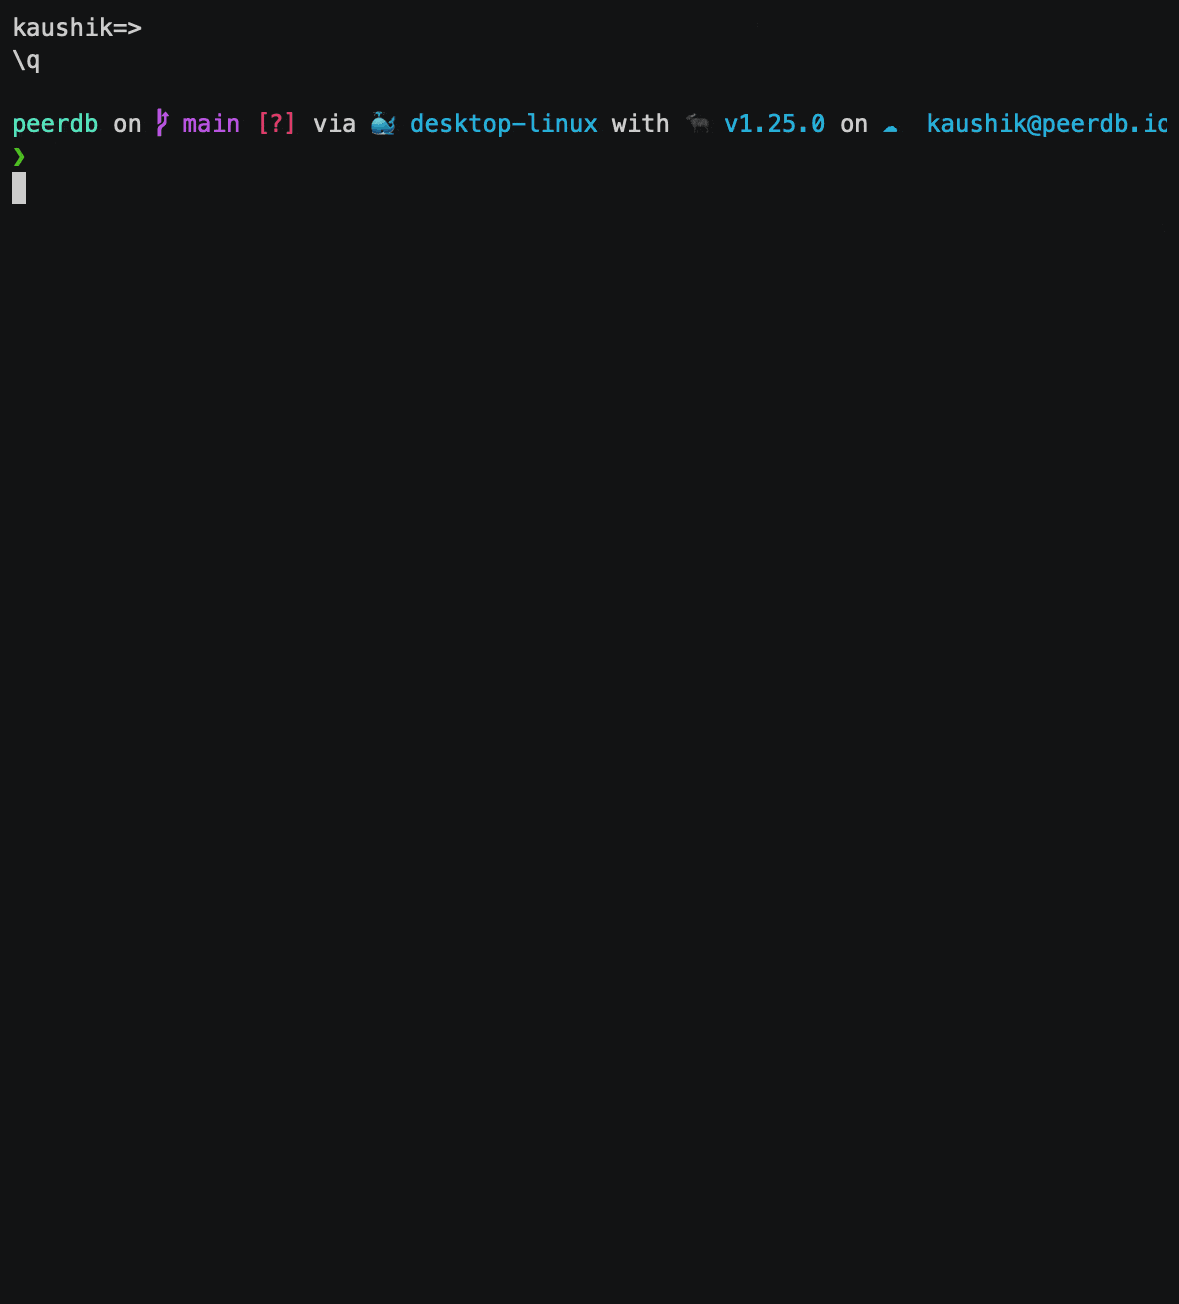
# Run docker containers: postgres as catalog, temporal, PeerDB server, PeerDB flow API + workers, PeerDB UI
# Requires docker and docker-compose installed: https://docs.docker.com/engine/install/
bash ./run-peerdb.sh
# OR for local development, images will be built locally.
# Requires docker, docker-compose as well as the buf compiler for protobuf generation
# https://buf.build/docs/installation
bash ./generate-protos.sh
bash ./dev-peerdb.sh

# connect to peerdb and query away (Use psql version >=14.0)
psql "port=9900 host=localhost password=peerdb"
IMPORTANT: Ensuring ClickHouse Access to MinIO
If your ClickHouse DB runs outside Docker (e.g., on VMs or ClickHouse Cloud), it may not have access to MinIO, which is used by PeerDB internally to stage files before loading them. Ensure ClickHouse has network access to MinIO.
PeerDB stages PostgreSQL data in MinIO within the Docker stack. Since ClickHouse is outside Docker, it needs a resolvable hostname for MinIO.
Update docker-compose.yml and set AWS_ENDPOINT_URL_S3 to MinIO's accessible IP (from both PeerDB and ClickHouse):
AWS_ENDPOINT_URL_S3: http://172.31.26.57:9001 # Change this to IP/host which is accessible by both PeerDB and ClickHouse
Rerun Docker Compose to apply changes. On AWS/GCP/Azure, also ensure the security group allows inbound access to MinIO.
Follow this 5-minute Quickstart Guide to see PeerDB in action i.e. streaming data in real-time across stores.
Why PeerDB
Current data tools prioritize a wide range of connectors, often neglecting to optimize for Postgres users. This can be problematic for those storing large amounts of data in Postgres and frequently transferring it. As a result, many resort to building custom pipelines when existing tools don't meet their needs. We've developed this project to provide a straightforward and reliable solution specifically for Postgres.
Postgres-first Approach
PeerDB is an ETL/ELT tool built for PostgreSQL. We implement multiple Postgres native and infrastructural optimizations to provide a fast, reliable and a feature-rich experience for moving data in/out of PostgreSQL.
For performance - we can parallelize initial load for a large table, still ensuring consistency. Syncing 100s of GB reduces from days to minutes. Our architecture is designed for real-time syncs and implements multiple logical replication related optimizations (e.g., tuning Postgres configs, parallel reading of slot). This enables 10x faster Change Data Capture with data-freshness of a few 10s of seconds even at large throughputs (10k+ tps).
For reliability, we have mechanisms in place for fault tolerance - state management, automatic retries, handling idempotency and consistency and so on (). Configurable batching and parallelism prevent out of memory (OOMs) and crashes.
From a feature richness standpoint, we support efficient syncing of tables with large (TOAST) columns. We support multiple streaming modes - log based (CDC), cursor based (timestamp or integer) and XMIN based (the cursor-based / Query Replication and XMIN modes are deprecated; CDC is recommended). We provide rich data-type mapping and plan to support every possible type (incl. Custom types) that Postgres supports to the best extent possible on the target data-store.
Now available natively in ClickHouse Cloud (Generally Available)
PeerDB is now available natively in ClickHouse Cloud (Generally Available). Learn more about it here.
Postgres-compatible SQL interface to do ETL
The Postgres-compatible SQL interface for ETL is unique to PeerDB and enables you to operate in a language you are familiar with. You can do ETL the same way you work with your databases.
You can use Postgres’ ecosystem to manage your ETL —
- Client tools like pgAdmin, psql to run SQL commands.
- BI tools like Grafana, Tableau to visually monitor syncs and transforms.
- Database migration and versioning tools like Flyway to manage your ETL.
- Any language (e.g., Python, Go, Node.js) and Scheduler (Airflow) for development.
- And many more.
Status
We have expanded our connector ecosystem to support multiple source connectors beyond Postgres, including MySQL, MongoDB, BigQuery, and CockroachDB. You can check the status of connectors here.
| Connector | Direction (source/destination) | Status |
|---|---|---|
| Postgres | Source | Actively maintained |
| MySQL | Source | Actively maintained |
| MongoDB | Source | Actively maintained |
| CockroachDB | Source | Actively maintained |
| BigQuery | Source | Actively maintained |
| ClickHouse | Destination | Actively maintained |
| ClickHouse Cloud | Destination | Actively maintained |
| Postgres | Destination | Actively maintained |
| S3 | Destination | Deprecated |
| Snowflake | Destination | Deprecated |
| BigQuery | Destination | Deprecated |
| ElasticSearch | Destination | Deprecated |
| Kafka | Destination | Deprecated |
| Redpanda | Destination | Deprecated |
| Confluent | Destination | Deprecated |
| Azure Event Hubs | Destination | Deprecated |
| Google Pub/Sub | Destination | Deprecated |
Local End to End testing
You can run locally the same end-to-end tests that our CI uses to validate changes, enabling fast iteration cycles during development.
For example:
cd flow
go clean -cache
go test -v -run TestGenericCH_MySQL ./e2e/
Or local debugging sessions.
These tests require both PeerDB services, source and destination stores to be running. We provide a local environment with all the necessary services and dependencies to run these tests.
This is done through Tilt orchestrated Docker compose.
To get the environment up you first need to specify the shared environment variables for both the test and the test environment in your local .env file. You can use the provided .env.example as a template: cp .env.example .env .
If a .env file is present in the project root, tests will automatically load it. Any variable defined in .env can be overridden by user-provided environment variables.
:memo: In the template, services URLs are set to `host.docker.interna