PDFLayoutTextStripper is a free, open source data extraction & web scraping project written in Java and released under Apache-2.0. It has 1,610 GitHub stars, 213 forks and 25 open issues, and was last pushed 37 hours ago. On this registry it ranks #89 of 145 tracked projects in Data Extraction & Web Scraping, with 5 head-to-head comparisons available.

What is PDFLayoutTextStripper?

PDFLayoutTextStripper is an Apache-2.0 Java library that converts a PDF file into a text file while keeping the layout of the original PDF, built as a subclass of the PDFTextStripper class from the Apache PDFBox library for developers who need to pull readable content out of tables and forms.

What it is

PDFLayoutTextStripper is a small Java library, licensed under Apache-2.0, that reads a PDF document and writes out text whose arrangement still mirrors the arrangement of the source document. It lives inside the Apache PDFBox ecosystem: the class extends PDFBox's PDFTextStripper, and the documented dependencies are Apache PDFBox itself together with commons-logging and fontbox. In an extraction pipeline it takes the place of the plain PDFTextStripper instance, which is exactly how the README's sample code uses it — a variable declared as PDFTextStripper is assigned a new PDFLayoutTextStripper, and getText is called on the resulting PDDocument.

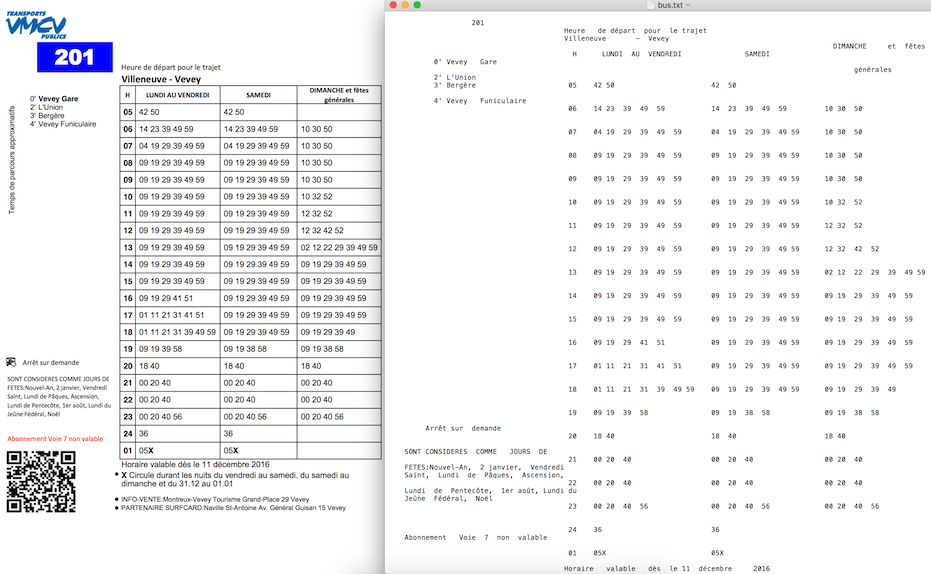
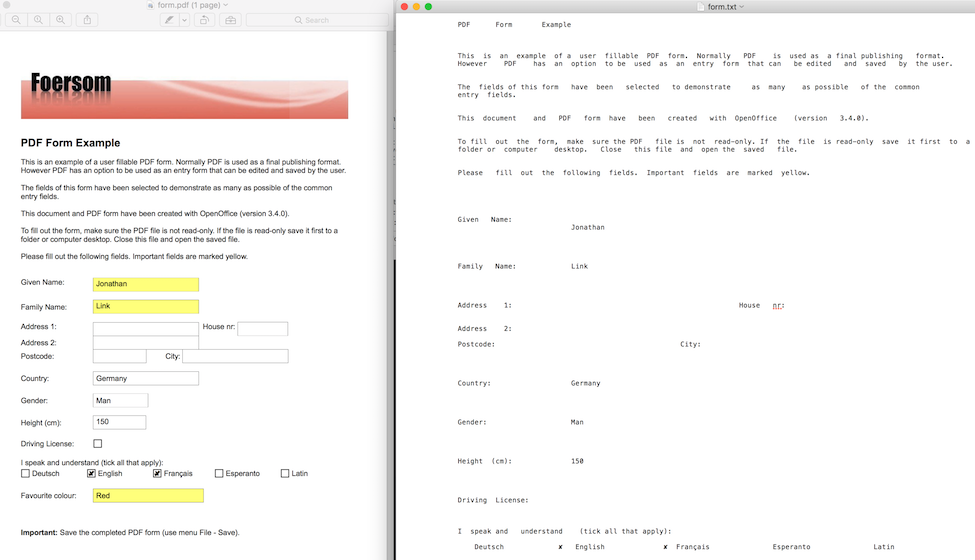
The problem it addresses is spatial. Ordinary text extraction flows a document's content in reading order, which is adequate for prose but flattens the row-and-column relationships of a table and separates the values of a form from the labels they belong to. By keeping the layout, the extracted text preserves those alignments, so the plain-text output can be read, diffed or parsed with the table structure still visible. The README names precisely two supported use cases: data extraction from a table in a PDF file, and data extraction from a form in a PDF file, each illustrated with a sample image.

Key capabilities

  • Produces text output that preserves the layout of the original PDF instead of emitting a reflowed stream of content.
  • Extends PDFTextStripper, so it is driven through the standard getText(PDDocument) call demonstrated in the sample code.
  • Is published to Maven as io.github.jonathanlink:PDFLayoutTextStripper, version 2.2.3.
  • Works with Apache PDFBox versions from 2.0.0 upwards; the manual instructions are written against pdfbox-2.0.6 alongside commons-logging.jar and fontbox-2.0.6.jar.
  • Targets two concrete extraction tasks documented in the README: content held in PDF tables and content held in PDF forms.
  • Runs from a plain javac and java invocation, with a colon-separated classpath on Linux and Mac and a semicolon-separated classpath on Windows.
  • Covers the data-extraction, layout and pdfbox topics listed for the repository, reflecting its narrow focus on text layout rather than general PDF manipulation.

Who uses it and how

  • Java developers who need the contents of a PDF table as plain text that still reads as a table, the scenario the README illustrates with its bus.pdf sample.
  • Teams extracting form content, where each value has to stay visually tied to the field it belongs to.
  • Projects already built on Apache PDFBox 2.x, which add the library as a Maven dependency rather than introducing a second PDF stack.
  • Scripted or command-line runs on Linux, macOS or Windows, using the documented javac and java commands and a hand-built classpath.
  • Codebases that already instantiate a PDFTextStripper and want layout preservation through a direct substitution of the subclass.

Getting started

Add the Maven dependency io.github.jonathanlink:PDFLayoutTextStripper:2.2.3, or install Apache PDFBox 2.0.0 or later with commons-logging and fontbox and compile and run the sources directly with javac and java, using a colon in the classpath on Linux and Mac and a semicolon on Windows.

How it compares

Among the tools named in the facts, its closest relative is Apache PDFBox itself: PDFLayoutTextStripper is a subclass of PDFBox's PDFTextStripper and is meant to be dropped in where that class would otherwise be used, so a project already on PDFBox gains layout-preserving output without changing its PDF engine. Its documented dependencies stay inside that same stack — PDFBox, commons-logging and fontbox — and the README credits Spire.PDF for Java as the project's sponsor, while the code itself remains Apache-2.0.

When to use it — and when not to

Choosing the manual installation route means sourcing pdfbox-2.0.6, commons-logging.jar and fontbox-2.0.6.jar yourself and compiling the sources by hand on the right classpath; there is no server, database or hosted service to run, but there is also no packaging beyond the Maven artifact and the raw Java files. Projects pinned to PDFBox versions below 2.0.0 cannot use this version, and anyone needing structured output such as JSON or HTML rather than a layout-preserving text file will have to post-process the result themselves. The README is short and version-pinned to one PDFBox release, and the repository currently carries 25 open issues, so teams that need extensive documentation or broad PDF feature coverage should evaluate PDFBox directly before adopting the subclass.

project readme (upstream, from github) — read inline

PDFLayoutTextStripper

Converts a PDF file into a text file while keeping the layout of the original PDF. Useful to extract the content from a table or a form in a PDF file. PDFLayoutTextStripper is a subclass of PDFTextStripper class (from the Apache PDFBox library).

This repository is supported by our sponsor
Spire.PDF for Java logo

Spire.PDF for Java

Create, edit, convert, and process PDF documents programmatically in Java, with support for tables, forms, images, annotations, and more.

Explore Spire.PDF for Java →

Use cases

Data extraction from a table in a PDF file example
Data extraction from a form in a PDF file example
How to install

Maven

<dependency>
  <groupId>io.github.jonathanlink</groupId>
  <artifactId>PDFLayoutTextStripper</artifactId>
  <version>2.2.3</version>
</dependency>

Manual

  1. Install apache pdfbox manually (to get the v2.0.6 click here ) and its two dependencies commons-logging.jar and fontbox

warning: only pdfbox versions from version 2.0.0 upwards are compatible with this version of PDFLayoutTextStripper.java

How to use on Linux/Mac

cd PDFLayoutTextStripper
javac -cp .:/pathto/pdfbox-2.0.6.jar:/pathto/commons-logging-1.2.jar:/pathto/PDFLayoutTextStripper/fontbox-2.0.6.jar *.java
java -cp .:/pathto/pdfbox-2.0.6.jar:/pathto/commons-logging-1.2.jar:/pathto/PDFLayoutTextStripper/fontbox-2.0.6.jar test

How to use on Windows

The same as for Linux (see above) but replace : with ;

Sample code

import java.io.File;
import java.io.FileNotFoundException;
import java.io.IOException;
import org.apache.pdfbox.io.RandomAccessFile;
import org.apache.pdfbox.pdfparser.PDFParser;
import org.apache.pdfbox.pdmodel.PDDocument;
import org.apache.pdfbox.text.PDFTextStripper;

public class test {
	public static void main(String[] args) {
		String string = null;
        try {
            PDFParser pdfParser = new PDFParser(new RandomAccessFile(new File("./samples/bus.pdf"), "r"));
            pdfParser.parse();
            PDDocument pdDocument = new PDDocument(pdfParser.getDocument());
            PDFTextStripper pdfTextStripper = new PDFLayoutTextStripper();
            string = pdfTextStripper.getText(pdDocument);
        } catch (FileNotFoundException e) {
            e.printStackTrace();
        } catch (IOException e) {
            e.printStackTrace();
        };
        System.out.println(string);
	}
}

Contributors

Thanks to

  • Dmytro Zelinskyy for reporting an issue with its correction (v2.2.3)
  • Ho Ting Cheng for reporting an issue (v2.1)
  • James Sullivan for having updated the code to make it work with the latest version of PDFBox (v2.0)

Frequently asked questions

Is PDFLayoutTextStripper free to use?

PDFLayoutTextStripper is open source under the Apache-2.0 licence. There is no licence fee and no seat count — you can self-host it or, where the project offers one, pay a vendor for a managed version instead.

What does PDFLayoutTextStripper do?

Converts a pdf file into a text file while keeping the layout of the original pdf. Useful to extract the content from a table in a pdf file for instance. This i

What is PDFLayoutTextStripper written in?

PDFLayoutTextStripper is primarily written in Java. Its source is publicly available at https://github.com/JonathanLink/PDFLayoutTextStripper, and it has 1,610 GitHub stars.