

Gatus is a developer-oriented health dashboard that gives you the ability to monitor your services using HTTP, ICMP, TCP, and even DNS queries as well as evaluate the result of said queries by using a list of conditions on values like the status code, the response time, the certificate expiration, the body and many others. The icing on top is that each of these health checks can be paired with alerting via Slack, Teams, PagerDuty, Discord, Twilio and many more.
I personally deploy it in my Kubernetes cluster and let it monitor the status of my core applications: https://status.twin.sh/
Looking for a managed solution? Check out Gatus.io.
Quick start
docker run -p 8080:8080 --name gatus ghcr.io/twin/gatus:stable
You can also use Docker Hub if you prefer:
docker run -p 8080:8080 --name gatus twinproduction/gatus:stable
For more details, see Usage
❤ Like this project? Please consider sponsoring me.
Have any feedback or questions? Create a discussion.
Table of Contents
- Table of Contents
- Why Gatus?
- Features
- Usage
- Configuration
- Endpoints
- External Endpoints
- Suites (ALPHA)
- Conditions
- Web
- UI
- Announcements
- Storage
- Client configuration
- Tunneling
- Alerting
- Configuring AWS SES alerts
- Configuring ClickUp alerts
- Configuring Datadog alerts
- Configuring Discord alerts
- Configuring Email alerts
- Configuring Gitea alerts
- Configuring GitHub alerts
- Configuring GitLab alerts
- Configuring Google Chat alerts
- Configuring Gotify alerts
- Configuring HomeAssistant alerts
- Configuring IFTTT alerts
- Configuring Ilert alerts
- Configuring Incident.io alerts
- Configuring Line alerts
- Configuring Matrix alerts
- Configuring Mattermost alerts
- Configuring Messagebird alerts
- Configuring n8n alerts
- Configuring New Relic alerts
- Configuring Ntfy alerts
- Configuring Opsgenie alerts
- Configuring PagerDuty alerts
- Configuring Plivo alerts
- Configuring Pushover alerts
- Configuring Rocket.Chat alerts
- Configuring SendGrid alerts
- Configuring Signal alerts
- Configuring SIGNL4 alerts
- Configuring Slack alerts
- Configuring Splunk alerts
- Configuring Squadcast alerts
- Configuring Teams alerts (Deprecated)
- Configuring Teams Workflow alerts
- Configuring Telegram alerts
- Configuring Twilio alerts
- Configuring Vonage alerts
- Configuring Webex alerts
- Configuring Zapier alerts
- Configuring Zulip alerts
- Configuring custom alerts
- Setting a default alert
- Maintenance
- Security
- TLS Encryption
- Metrics
- Connectivity
- Remote instances (EXPERIMENTAL)
- Deployment
- Running the tests
- Using in Production
- FAQ
- Sending a GraphQL request
- Recommended interval
- Default timeouts
- Monitoring a TCP endpoint
- Monitoring a UDP endpoint
- Monitoring a SCTP endpoint
- Monitoring a WebSocket endpoint
- Monitoring an endpoint using gRPC
- Monitoring an endpoint using ICMP
- Monitoring an endpoint using DNS queries
- Monitoring an endpoint using SSH
- Monitoring an endpoint using STARTTLS
- Monitoring an endpoint using TLS
- Monitoring domain expiration
- Concurrency
- Reloading configuration on the fly
- Endpoint groups
- How do I sort by group by default?
- Exposing Gatus on a custom path
- Exposing Gatus on a custom port
- Use environment variables in config files
- Configuring a startup delay
- Keeping your configuration small
- Proxy client configuration
- How to fix 431 Request Header Fields Too Large error
- Badges
- API
- Installing as binary
- High level design overview
Why Gatus?
Before getting into the specifics, I want to address the most common question:
Why would I use Gatus when I can just use Prometheus’ Alertmanager, Cloudwatch or even Splunk?
Neither of these can tell you that there’s a problem if there are no clients actively calling the endpoint. In other words, it's because monitoring metrics mostly rely on existing traffic, which effectively means that unless your clients are already experiencing a problem, you won't be notified.
Gatus, on the other hand, allows you to configure health checks for each of your features, which in turn allows it to monitor these features and potentially alert you before any clients are impacted.
A sign you may want to look into Gatus is by simply asking yourself whether you'd receive an alert if your load balancer was to go down right now. Will any of your existing alerts be triggered? Your metrics won’t report an increase in errors if no traffic makes it to your applications. This puts you in a situation where your clients are the ones that will notify you about the degradation of your services rather than you reassuring them that you're working on fixing the issue before they even know about it.
Features
The main features of Gatus are:
- Highly flexible health check conditions: While checking the response status may be enough for some use cases, Gatus goes much further and allows you to add conditions on the response time, the response body and even the IP address.
- Ability to use Gatus for user acceptance tests: Thanks to the point above, you can leverage this application to create automated user acceptance tests.
- Very easy to configure: Not only is the configuration designed to be as readable as possible, it's also extremely easy to add a new service or a new endpoint to monitor.
- Alerting: While having a pretty visual dashboard is useful to keep track of the state of your application(s), you probably don't want to stare at it all day. Thus, notifications via Slack, Mattermost, Messagebird, PagerDuty, Twilio, Google chat and Teams are supported out of the box with the ability to configure a custom alerting provider for any needs you might have, whether it be a different provider or a custom application that manages automated rollbacks.
- Metrics
- Low resource consumption: As with most Go applications, the resource footprint that this application requires is negligibly small.
- Badges:


- Dark mode
Usage
docker run -p 8080:8080 --name gatus ghcr.io/twin/gatus:stable
You can also use Docker Hub if you prefer:
docker run -p 8080:8080 --name gatus twinproduction/gatus:stable
If you want to create your own configuration, see Docker for information on how to mount a configuration file.
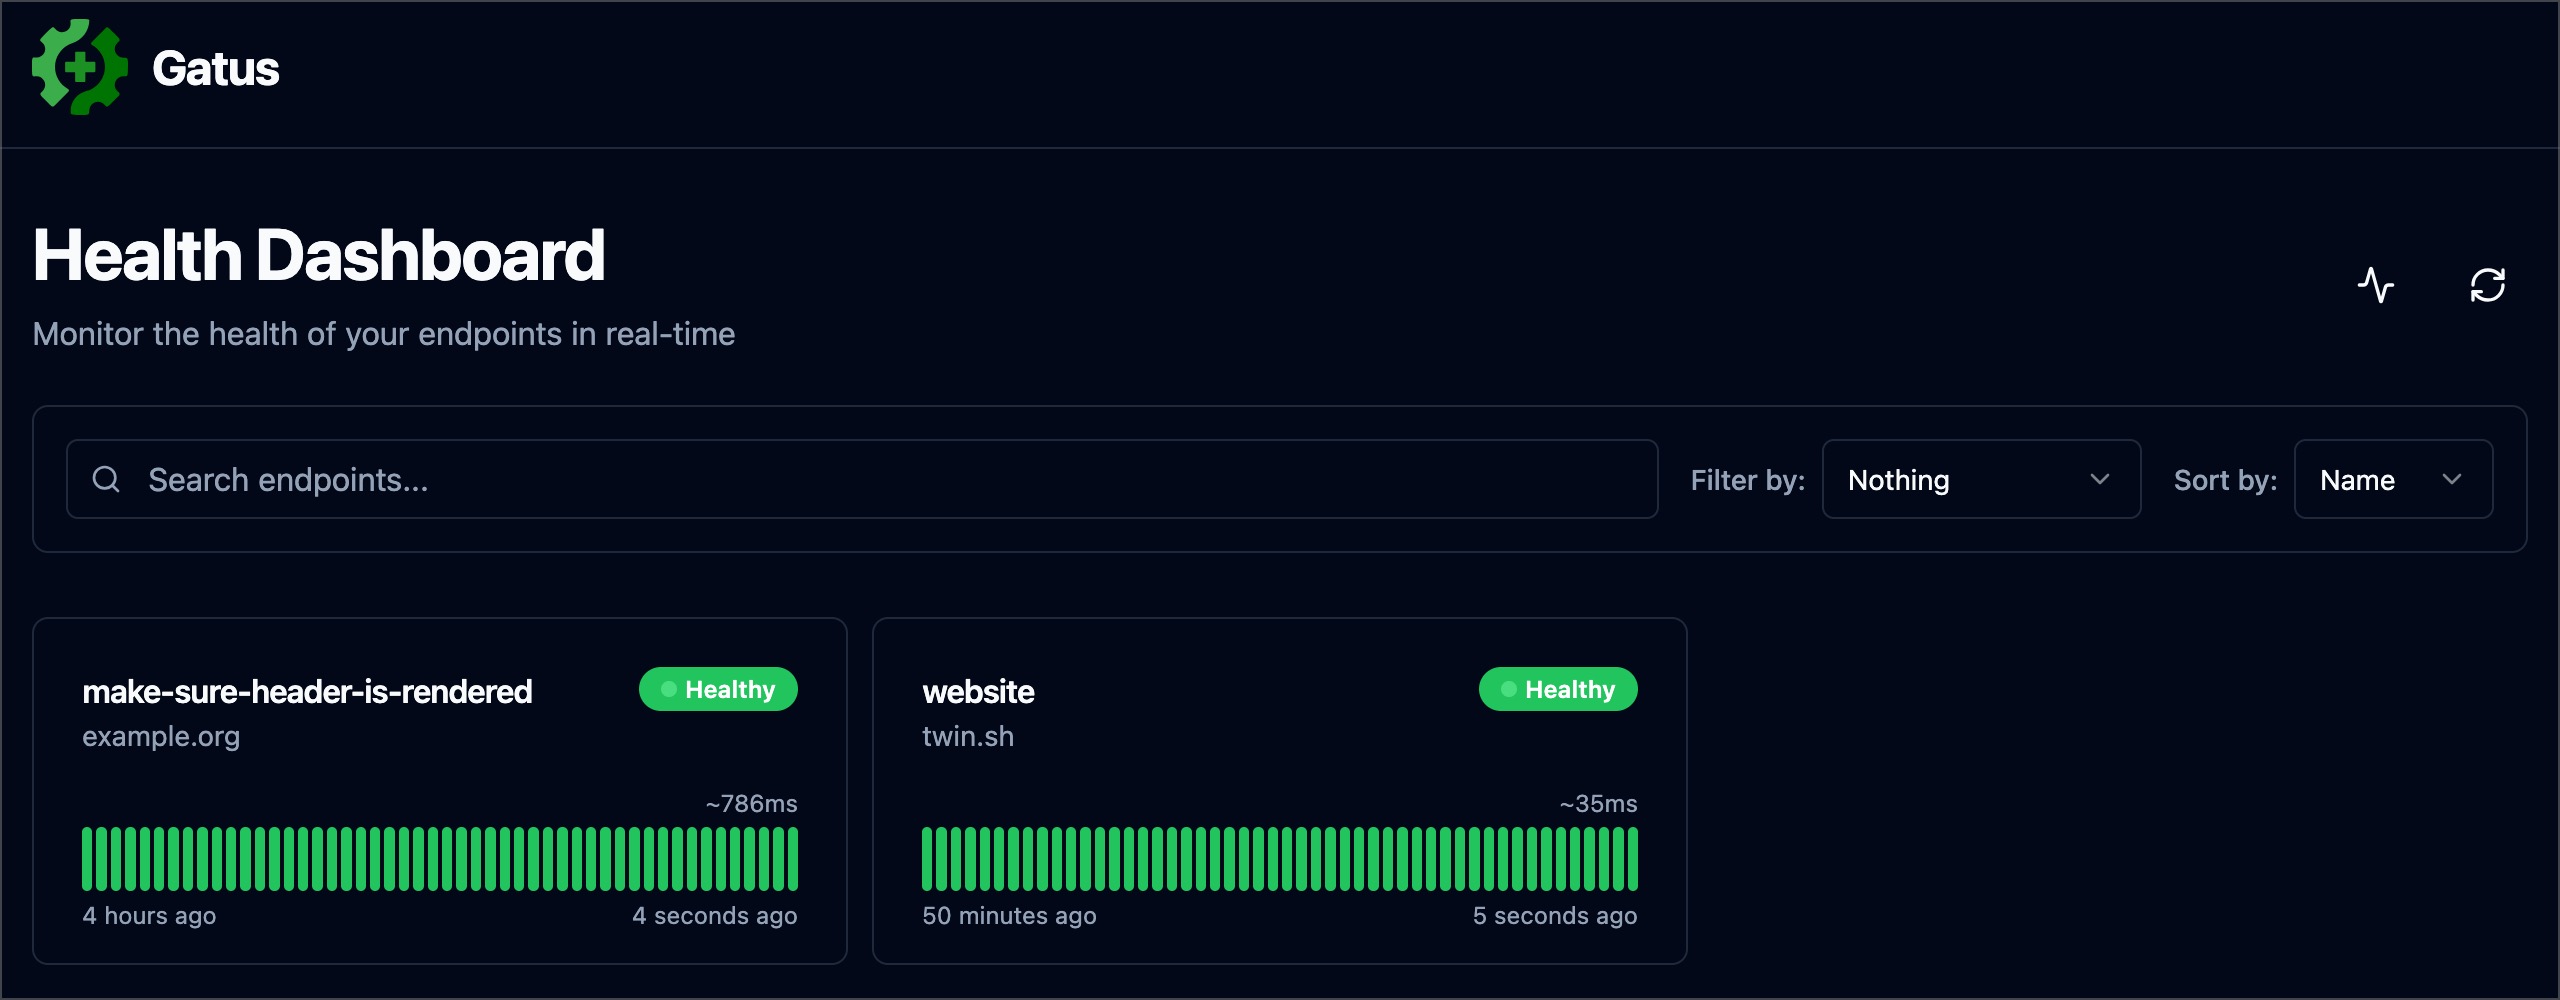
Here's a simple example:
endpoints:
  - name: website                 # Name of your endpoint, can be anything
    url: "https://twin.sh/health"
    interval: 5m                  # Duration to wait between every status check (default: 60s)
    conditions:
      - "[STATUS] == 200"         # Status must be 200
      - "[BODY].status == UP"     # The json path "$.status" must be equal to UP
      - "[RESPONSE_TIME] < 300"   # Response time must be under 300ms

  - name: make-sure-header-is-rendered
    url: "https://example.org/"
    interval: 60s
    conditions:
      - "[STATUS] == 200"                          # Status must be 200
      - "[BODY] == pat(*<h1>Example Domain</h1>*)" # Body must contain the specified header
This example would look similar to this:
If you want to test it locally, see Docker.
Configuration
By default, the configuration file is expected to be at config/config.yaml.
You can specify a custom path by setting the GATUS_CONFIG_PATH environment variable.
If GATUS_CONFIG_PATH points to a directory, all *.yaml and *.yml files inside said directory and its
subdirectories are merged like so:
- All maps/objects are deep merged (i.e. you could define
alerting.slackin one file andalerting.pagerdutyin another file) - All slices/arrays are appended (i.e. you can define
endpointsin multiple files and each endpoint will be added to the final list of endpoints) - Parameters with a primitive value (e.g.
metrics,alerting.slack.webhook-url, etc.) may only be defined once to forcefully avoid any ambiguity- To clarify, this also means that you could not define
alerting.slack.webhook-urlin two files with different values. All files are merged into one before they are processed. This is by design.
- To clarify, this also means that you could not define
💡 You can also use environment variables in the configuration file (e.g.
$DOMAIN,${DOMAIN})⚠️ When your configuration parameter contains a
$symbol, you have to escape$with$$.See Use environment variables in config files or examples/docker-compose-postgres-storage/config/config.yaml for examples.
If you want to test it locally, see Docker.
Configuration
| Parameter | Description | Default |
|---|---|---|
metrics |
Whether to expose metrics at /metrics. |
false |
storage |
Storage configuration. | {} |
alerting |
Alerting configuration. | {} |
announcements |
Announcements configuration. | [] |
endpoints |
Endpoints configuration. | Required [] |
external-endpoints |
External Endpoints configuration. | [] |
security |
Security configuration. | {} |
concurrency |
Maximum number of endpoints/suites to monitor concurrently. Set to 0 for unlimited. See Concurrency. |
3 |
disable-monitoring-lock |
Whether to disable the monitoring lock. Deprecated: Use concurrency: 0 instead. |
false |
skip-invalid-config-update |
Whether to ignore invalid configuration update. See Reloading configuration on the fly. |
false |
web |
Web configuration. | {} |
ui |
UI configuration. | {} |
maintenance |
Maintenance configuration. | {} |
If you want more verbose logging, you may set the GATUS_LOG_LEVEL environment variable to DEBUG.
Conversely, if you want less verbose logging, you can set the aforementioned environment variable to WARN, ERROR or FATAL.
The default value for GATUS_LOG_LEVEL is INFO.
Endpoints
Endpoints are URLs, applications, or services that you want to monitor. Each endpoint has a list of conditions that are evaluated on an interval that you define. If any condition fails, the endpoint is considered as unhealthy. You can then configure alerts to be triggered when an endpoint is unhealthy once a certain threshold is reached.
| Parameter | Description | Default |
|---|---|---|
endpoints |
List of endpoints to monitor. | Required [] |
endpoints[].enabled |
Whether to monitor the endpoint. | true |
endpoints[].name |
Name of the endpoint. Can be anything. | Required "" |
endpoints[].group |
Group name. Used to group multiple endpoints together on the dashboard. See Endpoint groups. |
"" |
endpoints[].url |
URL to send the request to. | Required "" |
endpoints[].method |
Request method. | GET |
endpoints[].conditions |
Conditions used to determine the health of the endpoint. See Conditions. |
[] |
endpoints[].interval |
Duration to wait between every status check. | 60s |
endpoints[].graphql |
Whether to wrap the body in a query param ({"query":"$body"}). |
false |
endpoints[].body |
Request body. | "" |
endpoints[].headers |
Request headers. | {} |
endpoints[].dns |
Configuration for an endpoint of type DNS. See Monitoring an endpoint using DNS queries. |
"" |
endpoints[].dns.query-type |
Query type (e.g. MX). | "" |
endpoints[].dns.query-name |
Query name (e.g. example.com). | "" |
endpoints[].ssh |
Configuration for an endpoint of type SSH. See Monitoring an endpoint using SSH. |
"" |
endpoints[].ssh.username |
SSH username (e.g. example). | Required "" |
endpoints[].ssh.password |
SSH password (e.g. password). | Required "" |
endpoints[].alerts |
List of all alerts for a given endpoint. See Alerting. |
[] |
endpoints[].maintenance-windows |
List of all maintenance windows for a given endpoint. See Maintenance. |
[] |
endpoints[].client |
Client configuration. | {} |
endpoints[].ui |
UI configuration at the endpoint level. | {} |
endpoints[].ui.hide-conditions |
Whether to hide conditions from the results. Note that this only hides conditions from results evaluated from the moment this was enabled. | false |
endpoints[].ui.hide-hostname |
Whether to hide the hostname from the results. | false |
endpoints[].ui.hide-port |
Whether to hide the port from the results. | false |
endpoints[].ui.hide-url |
Whether to hide the URL from the results. Useful if the URL contains a token. | false |
endpoints[].ui.hide-errors |
Whether to hide errors from the results. | false |
endpoints[].ui.dont-resolve-failed-conditions |
Whether to resolve failed conditions for the UI. | false |
endpoints[].ui.resolve-successful-conditions |
Whether to resolve successful conditions for the UI (helpful to expose body assertions even when checks pass). | false |
endpoints[].ui.badge.response-time |
List of response time thresholds. Each time a threshold is reached, the badge has a different color. | [50, 200, 300, 500, 750] |
endpoints[].extra-labels |
Extra labels to add to the metrics. Useful for grouping endpoints together. | {} |
endpoints[].always-run |
(SUITES ONLY) Whether to execute this endpoint even if previous endpoints in the suite failed. | false |
endpoints[].store |
(SUITES ONLY) Map of values to extract from the response and store in the suite context (stored even on failure). | {} |
You may use the following placeholders in the body (endpoints[].body):
[ENDPOINT_NAME](resolved fromendpoints[].name)[ENDPOINT_GROUP](resolved fromendpoints[].group)[ENDPOINT_URL](resolved fromendpoints[].url)[LOCAL_ADDRESS](resolves to the local IP and port like192.0.2.1:25or[2001:db8::1]:80)[RANDOM_STRING_N](resolves to a random string of numbers and letters of length N (max: 8192))
External Endpoints
Unlike regular endpoints, external endpoints are not monitored by Gatus, but they are instead pushed programmatically. This allows you to monitor anything you want, even when what you want to check lives in an environment that would not normally be accessible by Gatus.
For instance:
- You can create your own agent that lives in a private network and pushes the status of your services to a publicly-exposed Gatus instance
- You can monitor services that are not supported by Gatus
- You can implement your own monitoring system while using Gatus as the dashboard
| Parameter | Description | Default |
|---|---|---|
external-endpoints |
List of endpoints to monitor. | [] |
external-endpoints[].enabled |
Whether to monitor the endpoint. | true |
external-endpoints[].name |
Name of the endpoint. Can be anything. | Required "" |
external-endpoints[].group |
Group name. Used to group multiple endpoints together on the dashboard. See Endpoint groups. |
"" |
external-endpoints[].token |
Bearer token required to push status to. | Required "" |
external-endpoints[].alerts |
List of all alerts for a given endpoint. See Alerting. |
[] |
external-endpoints[].heartbeat |
Heartbeat configuration for monitoring when the external endpoint stops sending updates. | {} |
external-endpoints[].heartbeat.interval |
Expected interval between updates. If no update is received within this interval, alerts will be triggered. Must be at least 10s. | 0 (disabled) |
Example:
external-endpoints:
  - name: ext-ep-test
    group: core
    token: "potato"
    heartbeat:
      interval: 30m  # Automatically create a failure if no update is received within 30 minutes
    alerts:
      - type: discord
        description: "healthcheck failed"
        send-on-resolved: true
To push the status of an external endpoint, you can use gatus-cli:
gatus-cli external-endpoint push --url https://status.example.org --key "core_ext-ep-test" --token "potato" --success
or send an HTTP request:
POST /api/v1/endpoints/{key}/external?success={success}&error={error}&duration={duration}
Where:
{key}has the pattern_in which both variables have/,_,,,.,#,+and&replaced by-.- Using the example configuration above, the key would be
core_ext-ep-test.
- Using the example configuration above, the key would be
{success}is a boolean (trueorfalse) value indicating whether the health check was successful or not.{error}(optional): a string describing the reason for a failed health check. If {success} is false, this should contain the error message; if the check is successful, this will be ignored.{duration}(optional): the time that the request took as a duration string (e.g. 10s).
You must also pass the token as a Bearer token in the Authorization header.
Suites (ALPHA)
Suites are collections of endpoints that are executed sequentially with a shared context. This allows you to create complex monitoring scenarios where the result from one endpoint can be used in subsequent endpoints, enabling workflow-style monitoring.
Here are a few cases in which suites could be useful:
- Testing multi-step authentication flows (login -> access protected resource -> logout)
- API workflows where you need to chain requests (create resource -> update -> verify -> delete)
- Monitoring business processes that span multiple services
- Validating data consistency across multiple endpoints
| Parameter | Description | Default |
|---|---|---|
suites |
List of suites to monitor. | [] |
suites[].enabled |
Whether to monitor the suite. | true |
suites[].name |
Name of the suite. Must be unique. | Required "" |
suites[].group |
Group name. Used to group multiple suites together on the dashboard. | "" |
suites[].interval |
Duration to wait between suite executions. | 10m |
suites[].timeout |
Maximum duration for the entire suite execution. | 5m |
suites[].context |
Initial context values that can be referenced by endpoints. | {} |
suites[].endpoints |
List of endpoints to execute sequentially. | Required [] |
suites[].endpoints[].store |
Map of values to extract from the response and store in the suite context (stored even on failure). | {} |
suites[].endpoints[].always-run |
Whether to execute this endpoint even if previous endpoints in the suite failed. | false |
Note: Suite-level alerts are not supported yet. Configure alerts on individual endpoints within the suite instead.
Using Context in Endpoints
Once values are stored in the context, they can be referenced in subsequent endpoints:
- In the URL:
https://api.example.com/users/[CONTEXT].user_id - In headers:
Authorization: Bearer [CONTEXT].auth_token - In the body:
{"user_id": "[CONTEXT].user_id"} - In conditions:
[BODY].server_ip == [CONTEXT].server_ip
Note that context/store keys are limited to A-Z, a-z, 0-9, underscores (_), and hyphens (-).
Example Suite Configuration
suites:
  - name: item-crud-workflow
    group: api-tests
    interval: 5m
    context:
      price: "19.99"  # Initial static value in context
    endpoints:
      # Step 1: Create an item and store the item ID
      - name: create-item
        url: https://api.example.com/items
        method: POST
        body: '{"name": "Test Item", "price": "[CONTEXT].price"}'
        conditions:
          - "[STATUS] == 201"
          - "len([BODY].id) > 0"
          - "[BODY].price == [CONTEXT].price"
        store:
          itemId: "[BODY].id"
        alerts:
          - type: slack
            description: "Failed to create item"

      # Step 2: Update the item using the stored item ID
      - name: update-item
        url: https://api.example.com/items/[CONTEXT].itemId
        method: PUT
        body: '{"price": "24.99"}'
        conditions:
          - "[STATUS] == 200"
        alerts:
          - type: slack
            description: "Failed to update item"

      # Step 3: Fetch the item and validate the price
      - name: get-item
        url: https://api.example.com/items/[CONTEXT].itemId
        method: GET
        conditions:
          - "[STATUS] == 200"
          - "[BODY].price == 24.99"
        alerts:
          - type: slack
            description: "Item price did not update correctly"

      # Step 4: Delete the item (always-run: true to ensure cleanup even if step 2 or 3 fails)
      - name: delete-item
        url: https://api.example.com/items/[CONTEXT].itemId
        method: DELETE
        always-run: true
        conditions:
          - "[STATUS] == 204"
        alerts:
          - type: slack
            description: "Failed to delete item"
The suite will be considered successful only if all required endpoints pass their conditions.
Conditions
Here are some examples of conditions you can use:
| Condition | Description | Passing values | Failing values |
|---|---|---|---|
[STATUS] == 200 |
Status must be equal to 200 | 200 | 201, 404, ... |
[STATUS] 400 |
Status must be greater than 400 | 401, 402, 403, 404 | 400, 200, ... |
[STATUS] == any(200, 429) |
Status must be either 200 or 429 | 200, 429 | 201, 400, ... |
[CONNECTED] == true |
Connection to host must've been successful | true | false |
[RESPONSE_TIME] 48h |
Certificate expiration is more than 48h away | 49h, 50h, 123h | 1h, 24h, ... |
[DOMAIN_EXPIRATION] > 720h |
The domain must expire in more than 720h | 4000h | 1h, 24h, ... |
Placeholders
| Placeholder | Description | Example of resolved value |
|---|---|---|
[STATUS] |
Resolves into the HTTP status of the request | 404 |
[RESPONSE_TIME] |
Resolves into the response time the request took, in ms | 10 |
[IP] |
Resolves into the IP of the target host | 192.168.0.232 |
[BODY] |
Resolves into the response body. Supports JSONPath. | {"name":"john.doe"} |
[CONNECTED] |
Resolves into whether a connection could be established | true |
[CERTIFICATE_EXPIRATION] |
Resolves into the duration before certificate expiration (valid units are "s", "m", "h".) | 24h, 48h, 0 (if not protocol with certs) |
[DOMAIN_EXPIRATION] |
Resolves into the duration before the domain expires (valid units are "s", "m", "h".) | 24h, 48h, 1234h56m78s |
[DNS_RCODE] |
Resolves into the DNS status of the response | NOERROR |
Functions
| Function | Description | Example |
|---|---|---|
len |
If the given path leads to an array, returns its length. Otherwise, the JSON at the given path is minified and converted to a string, and the resulting number of characters is returned. Works only with the [BODY] placeholder. |
len([BODY].username) > 8 |
has |
Returns true or false based on whether a given path is valid. Works only with the [BODY] placeholder. |
has([BODY].errors) == false |
pat |
Specifies that the string passed as parameter should be evaluated as a pattern. Works only with == and !=. |
[IP] == pat(192.168.*) |
any |
Specifies that any one of the values passed as parameters is a valid value. Works only with == and !=. |
[BODY].ip == any(127.0.0.1, ::1) |
💡 Use
patonly when you need to.[STATUS] == pat(2*)is a lot more expensive than[STATUS] Only supported ifstorage.typeissqliteorpostgres|false| |storage.maximum-number-of-results| The maximum number of results that an endpoint can have |100| |storage.maximum-number-of-events| The maximum number of events that an endpoint can have |50` |
The results for each endpoint health check as well as the data for uptime and the past events must be persisted so that they can be displayed on the dashboard. These parameters allow you to configure the storage in question.
- If
storage.typeismemory(default):
# Note that this is the default value, and you can omit the storage configuration altogether to achieve the same result.
# Because the data is stored in memory, the data will not survive a restart.
storage:
  type: memory
  maximum-number-of-results: 200
  maximum-number-of-events: 5
- If
storage.typeissqlite,storage.pathmust not be blank:
storage:
  type: sqlite
  path: data.db
See examples/docker-compose-sqlite-storage for an example.
- If
storage.typeispostgres,storage.pathmust be the connection URL:
storage:
  type: postgres
  path: "postgres://user:password@127.0.0.1:5432/gatus?sslmode=disable"
See examples/docker-compose-postgres-storage for an example.
Client configuration
In order to support a wide range of environments, each monitored endpoint has a unique configuration for the client used to send the request.
| Parameter | Description | Default |
|---|---|---|
client.insecure |
Whether to skip verifying the server's certificate chain and host name. | false |
client.ignore-redirect |
Whether to ignore redirects (true) or follow them (false, default). | false |
client.timeout |
Duration before timing out. | 10s |
client.dns-resolver |
Override the DNS resolver using the format {proto}://{host}:{port}. |
"" |
client.oauth2 |
OAuth2 client configuration. | {} |
client.oauth2.token-url |
The token endpoint URL | required "" |
client.oauth2.client-id |
The client id which should be used for the Client credentials flow |
required "" |
client.oauth2.client-secret |
The client secret which should be used for the Client credentials flow |
required "" |
client.oauth2.scopes[] |
A list of scopes which should be used for the Client credentials flow. |
required [""] |
client.proxy-url |
The URL of the proxy to use for the client | "" |
client.identity-aware-proxy |
Google Identity-Aware-Proxy client configuration. | {} |
client.identity-aware-proxy.audience |
The Identity-Aware-Proxy audience. (client-id of the IAP oauth2 credential) | required "" |
client.tls.certificate-file |
Path to a client certificate (in PEM format) for mTLS configurations. | "" |
client.tls.private-key-file |
Path to a client private key (in PEM format) for mTLS configurations. | "" |
client.tls.renegotiation |
Type of renegotiation support to provide. (never, freely, once). |
"never" |
client.network |
The network to use for ICMP endpoint client (ip, ip4 or ip6). |
"ip" |
client.tunnel |
Name of the SSH tunnel to use for this endpoint. See Tunneling. | "" |
client.store-cookies |
Whether to store cookies between requests. | false |
📝 Some of these parameters are ignored based on the type of endpoint. For instance, there's no certificate involved in ICMP requests (ping), therefore, setting
client.insecuretotruefor an endpoint of that type will not do anything.
This default configuration is as follows:
client:
  insecure: false
  ignore-redirect: false
  timeout: 10s
  store-cookies: false
Note that this configuration is only available under endpoints[], alerting.mattermost and alerting.custom.
Here's an example with the client configuration under endpoints[]:
endpoints:
  - name: website
    url: "https://twin.sh/health"
    client:
      insecure: false
      ignore-redirect: false
      timeout: 10s
    conditions:
      - "[STATUS] == 200"
This example shows how you can specify a custom DNS resolver:
endpoints:
  - name: with-custom-dns-resolver
    url: "https://your.health.api/health"
    client:
      dns-resolver: "tcp://8.8.8.8:53"
    conditions:
      - "[STATUS] == 200"
This example shows how you can use the client.oauth2 configuration to query a backend API with Bearer token:
endpoints:
  - name: with-custom-oauth2
    url: "https://your.health.api/health"
    client:
      oauth2:
        token-url: https://your-token-server/token
        client-id: 00000000-0000-0000-0000-000000000000
        client-secret: your-client-secret
        scopes: ['https://your.health.api/.default']
    conditions:
      - "[STATUS] == 200"
This example shows how you can use the client.identity-aware-proxy configuration to query a backend API with Bearer token using Google Identity-Aware-Proxy:
endpoints:
  - name: with-custom-iap
    url: "https://my.iap.protected.app/health"
    client:
      identity-aware-proxy:
        audience: "XXXXXXXX-XXXXXXXXXXXX.apps.googleusercontent.com"
    conditions:
      - "[STATUS] == 200"
📝 Note that Gatus will use the gcloud default credentials within its environment to generate the token.
This example shows you how you can use the client.tls configuration to perform an mTLS query to a backend API:
endpoints:
  - name: website
    url: "https://your.mtls.protected.app/health"
    client:
      tls:
        certificate-file: /path/to/user_cert.pem
        private-key-file: /path/to/user_key.pem
        renegotiation: once
    conditions:
      - "[STATUS] == 200"
📝 Note that if running in a container, you must volume mount the certificate and key into the container.
Tunneling
Gatus supports SSH tunneling to monitor internal services through jump hosts or bastion servers. This is particularly useful for monitoring services that are not directly accessible from where Gatus is deployed.
SSH tunnels are defined globally in the tunneling section and then referenced by name in endpoint client configurations.
| Parameter | Description | Default |
|---|---|---|
tunneling |
SSH tunnel configurations | {} |
tunneling. |
Configuration for a named SSH tunnel | {} |
tunneling..type |
Type of tunnel (currently only SSH is supported) |
Required "" |
tunneling..host |
SSH server hostname or IP address | Required "" |
tunneling..port |
SSH server port | 22 |
tunneling..username |
SSH username | Required "" |
tunneling..password |
SSH password (use either this or private-key) | "" |
tunneling..private-key |
SSH private key in PEM format (use either this or password) | "" |
client.tunnel |
Name of the tunnel to use for this endpoint | "" |
tunneling:
  production:
    type: SSH
    host: "jumphost.example.com"
    username: "monitoring"
    private-key: |
      -----BEGIN RSA PRIVATE KEY-----
      MIIEpAIBAAKCAQEA...
      -----END RSA PRIVATE KEY-----

endpoints:
  - name: "internal-api"
    url: "http://internal-api.example.com:8080/health"
    client:
      tunnel: "production"
    conditions:
      - "[STATUS] == 200"
⚠️ WARNING:: Tunneling may introduce additional latency, especially if the connection to the tunnel is retried frequently. This may lead to inaccurate response time measurements.
Alerting
Gatus supports multiple alerting providers, such as Slack and PagerDuty, and supports different alerts for each individual