Bruin is an open-source data pipeline tool that brings data ingestion, SQL, Python and R transformation, and data quality checks into a single framework, written in Go and aimed at data engineers and analytics teams building pipelines on platforms such as BigQuery and Snowflake.
What it is
Bruin is a data pipeline tool distributed under the Apache-2.0 licence and implemented in Go. It unifies three jobs that are usually handled by separate pieces of software: pulling data in from external sources, transforming it with SQL, Python or R, and asserting quality on the results. The same framework covers ingestion through ingestr or Python, transformations across many supported platforms, and built-in quality checks, so a pipeline is described, validated and run as one unit rather than as a chain of unrelated jobs.
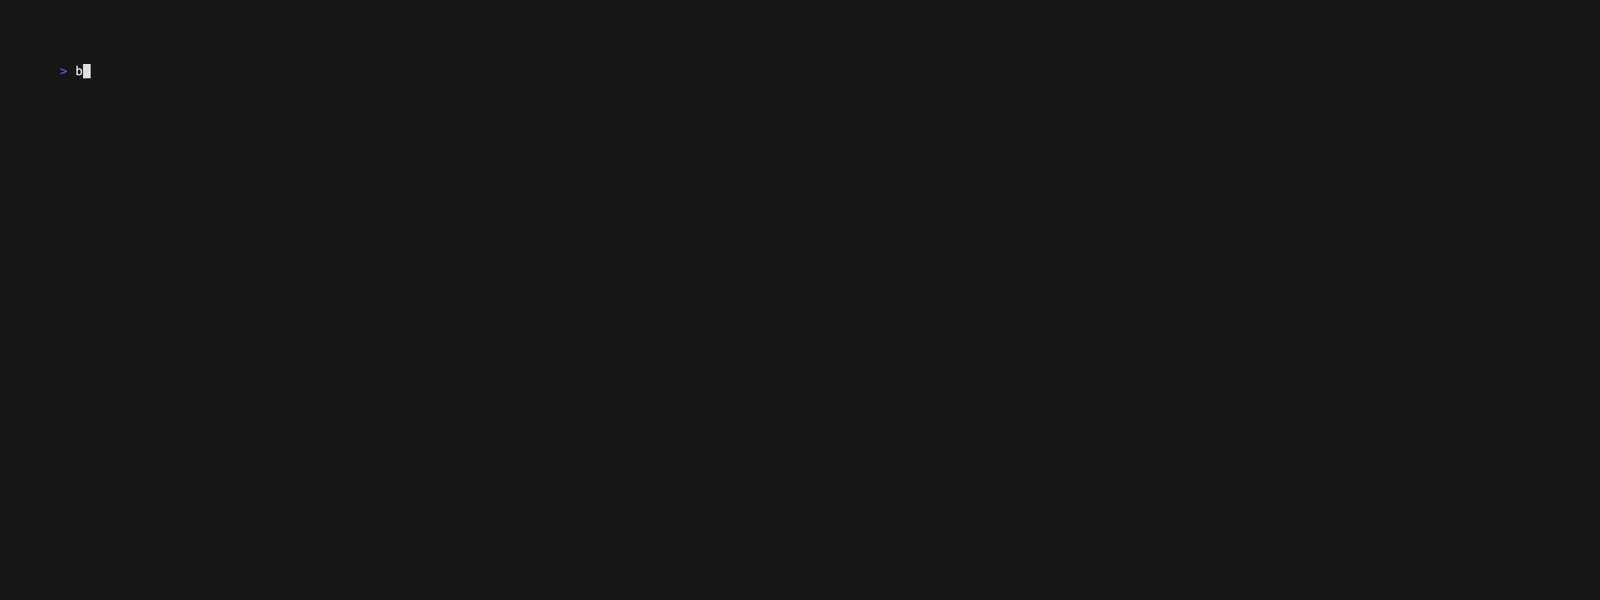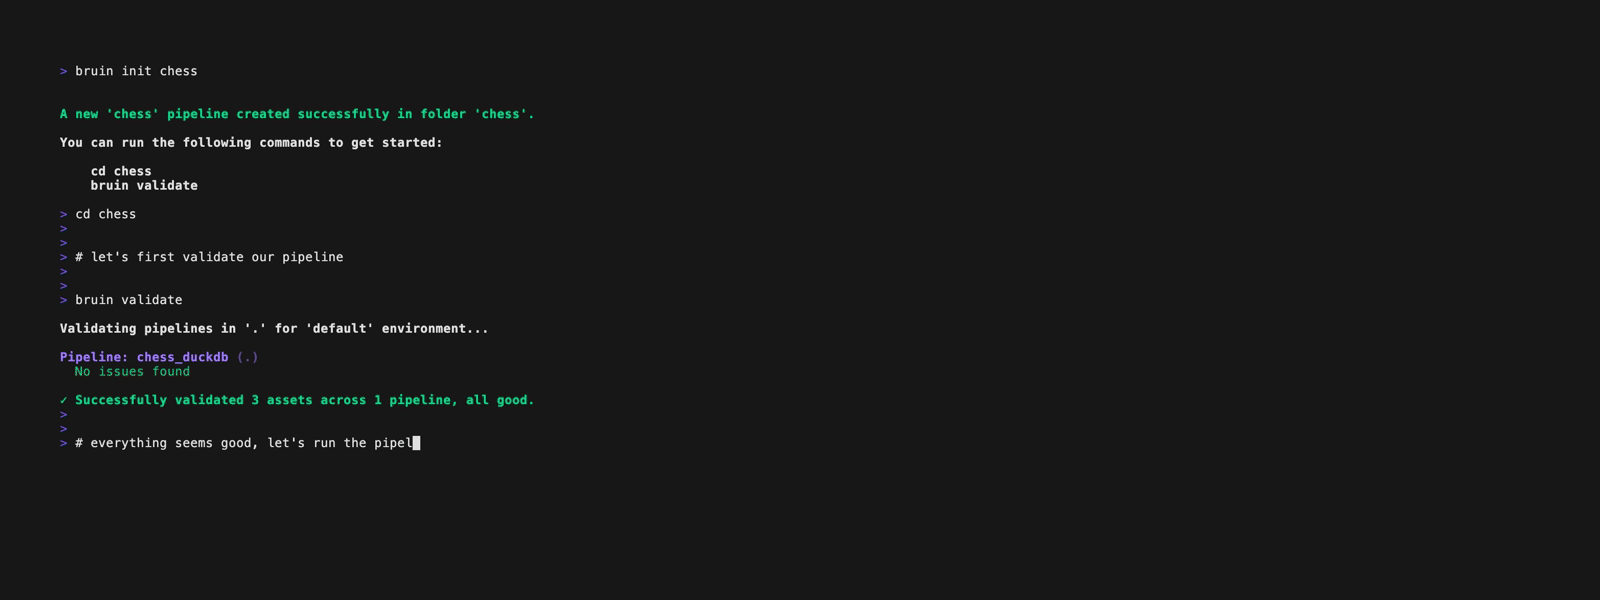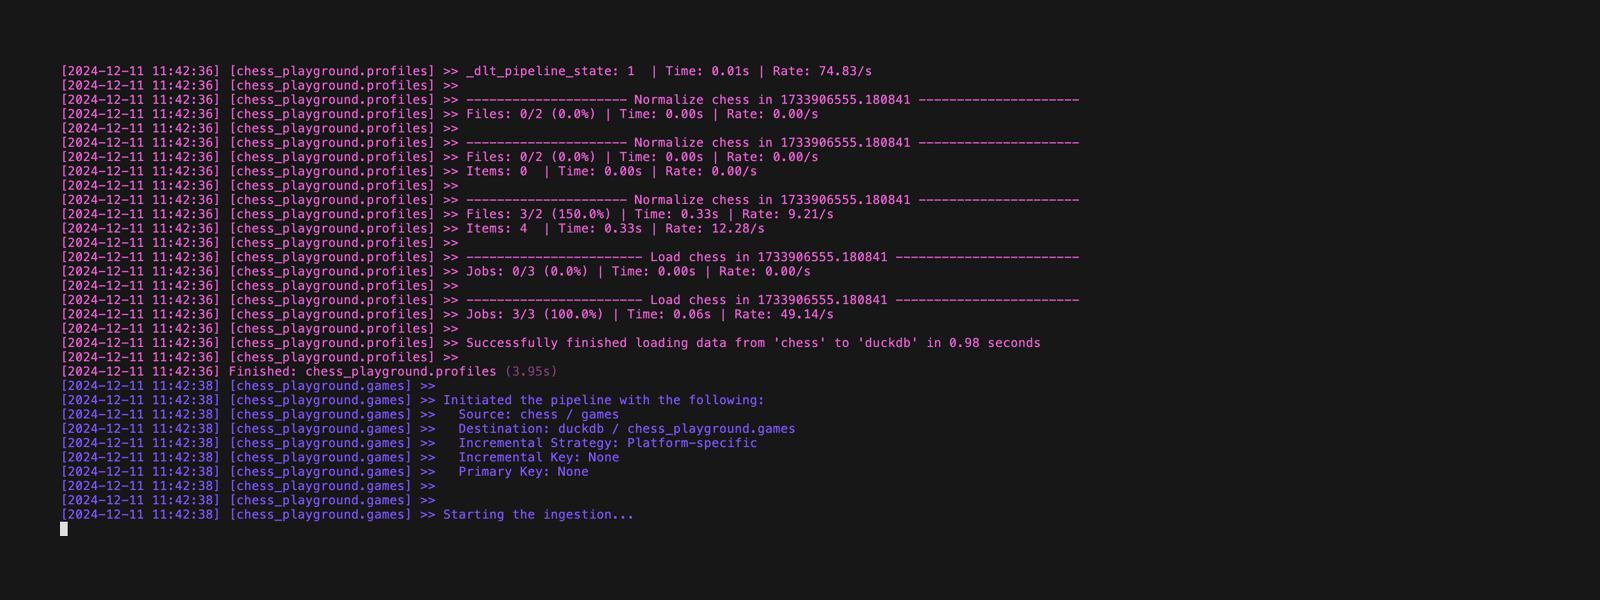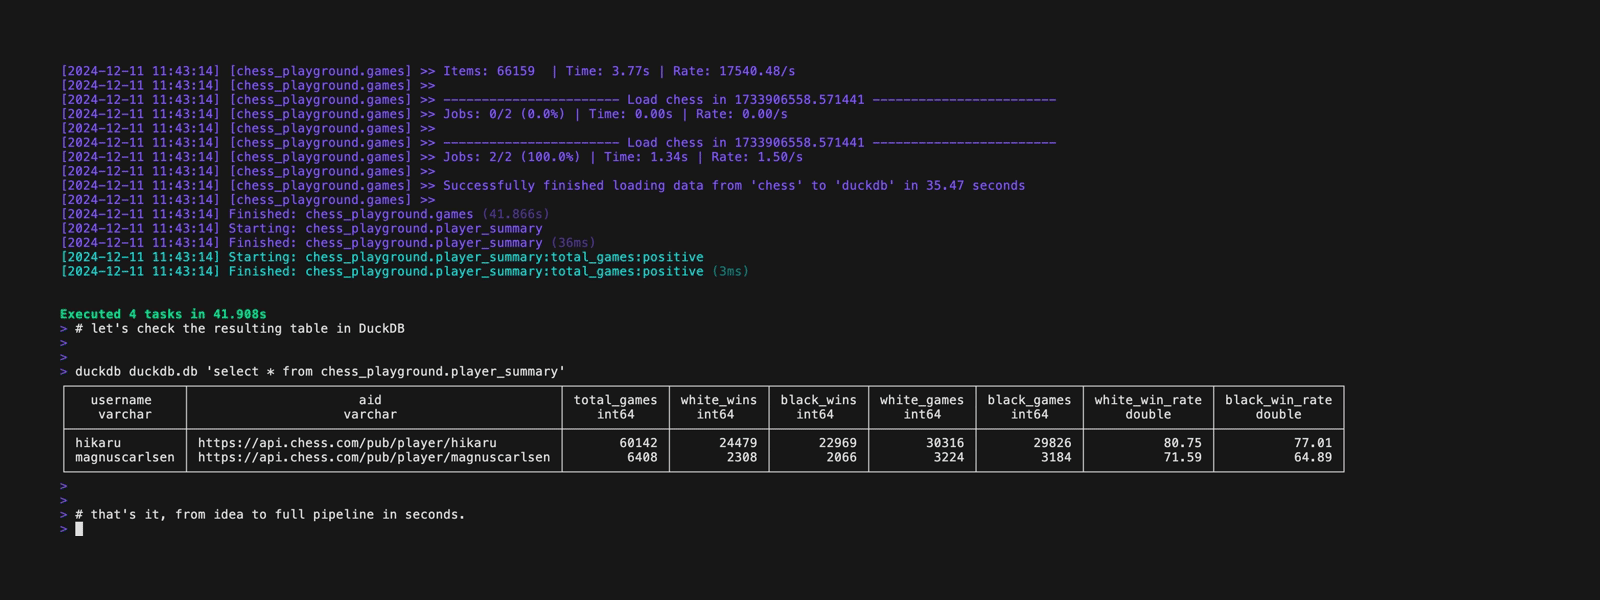
The concrete problem it solves is the assembly work around analytics engineering. Instead of wiring an ingestion tool to a transformation tool to a separate testing layer, and then keeping their schedules, credentials and failure modes in sync, Bruin expresses all of that in one project. It supports table and view materializations and incremental tables, renders pipelines with Jinja templating to avoid repetition, and lets a pipeline be validated end to end with a dry-run before anything is executed. It lives in the modern data stack around BigQuery, Snowflake and similar platforms, and it runs on a local machine, an EC2 instance, or GitHub Actions.
Key capabilities
- Ingest data with ingestr or Python as the first stage of a pipeline.
- Run SQL, Python and R transformations against many supported data platforms.
- Define table and view materializations, including incremental tables.
- Execute Python in isolated environments using uv.
- Apply built-in data quality checks inside the pipeline definition.
- Use Jinja templating to avoid repeating pipeline logic.
- Validate pipelines end to end via dry-run, and inject secrets through environment variables.
Who uses it and how
- Data engineers building and maintaining pipelines on platforms such as BigQuery and Snowflake, where transformations and quality checks must live alongside ingestion.
- Analytics teams that want transformation logic written in SQL, Python or R within one project rather than split across tools.
- Teams running pipelines on a local machine or an EC2 instance when a managed orchestrator is not part of the setup.
- Teams wiring pipelines into CI/CD through the GitHub Actions integration.
- Developers who want editor-level support while authoring pipelines, via the VS Code extension.
Getting started
Installation follows the instructions in the Bruin documentation, and a quickstart guide walks through the first pipeline. There is no hosted option described in the material provided; the README points to the installation page and the quickstart.
How it compares
No list of paid products that Bruin replaces is provided in the available facts, and no comparable tools are named either. It stands alone in this registry on that basis.
When to use it — and when not to
A self-hoster has to supply the execution environment, whether that is a local machine, an EC2 instance or GitHub Actions, and has to manage credentials through environment variables, since no managed hosting is described. Teams that want a fully managed pipeline service, or that already standardise on a different orchestration stack, are not the intended audience. The README itself is a feature summary rather than a deep reference, and the project carries a notable open-issue count, so anyone evaluating it should read the documentation site before committing.