🧠 Agent Memory Techniques
Learn every agent memory technique for LLM agents.
⭐ If you find this useful, please star the repo so more learners can discover it.
🧭 New here? Start with 01 Conversation Buffer Memory or pick a Learning Path. Prefer a visual? See the Decision Tree below. 30 runnable Jupyter notebooks covering conversation buffers, vector stores, knowledge graphs, episodic and semantic memory, working memory, MemGPT, Mem0, Letta, Zep, Graphiti, LoCoMo benchmarks, and production memory patterns.




🎓 From memory demos to production agents
Prompt to Production - my full course on building software with AI the way professionals do: the methods and paradigms behind reliable, efficient, modular production systems, taught systematically. 17 modules, each pairing a video lecture with a hands-on lab, from your first structured prompt to a working production system.
The course is live. Every module is out, lecture and lab.
🎁 Try a full module, free
| 🎬 7-minute video lecture |
🛠️ Hands-on tutorial |
🤖 AI assistant inside Claude Code |
One npm install adds the module's AI assistant to your Claude Code, and it guides you through the tutorial as you build.
👉 Get the full course
📖 The book of this repo
Agent Memory Made Simple - the 464-page visual guide to everything in this repo: all 30 techniques, 184 custom illustrations, zero code required.
Get it on Amazon (paperback · Kindle · free on Kindle Unlimited) →
More from the series: RAG Made Simple - Amazon Bestseller in Generative AI · 1,500+ readers · ⭐ 4.6
📫 Stay Updated
| 🚀 Weekly Updates |
💡 Expert Insights |
🎯 Top 0.1% Content |
Join over 50,000 readers getting clear AI tutorials every week. Subscribers also get early access and a 33% discount on my book.
💡 Why Agent Memory Matters
💡 Quick Answer (for search engines and skimmers)
Agent memory is the set of techniques that let an LLM-based agent (a system built around a Large Language Model) remember information across turns, sessions, and tasks. Without memory, an agent re-derives context every time and cannot personalize, learn, or maintain coherence over long interactions. This repository documents 30 distinct memory techniques, grouped into six families: short-term context management, long-term storage, cognitive architectures, retrieval and multi-agent patterns, batteries-included frameworks, and production deployment patterns.
Think about a friend who forgets every conversation you've ever had. Every morning you're strangers again. That's what most AI agents are like today.
Every AI agent eventually hits the same wall: it forgets.
In 2026, AI agents are everywhere. But most of them still forget what you told them yesterday. Without strong memory, an agent can't keep context across conversations. It can't learn from past chats. It can't build a lasting relationship with you.
The landscape is shifting fast:
- Anthropic's 7 Layers of Memory (March 2026): from conversation context to cross-project knowledge, defining the memory hierarchy for Claude Code
- Mem0: managed memory layer gaining rapid adoption for personalized AI
- Letta (MemGPT): self-editing memory with inner/outer monologue architecture
- Zep: temporal knowledge graphs for long-term agent memory
- Graphiti: episodic-to-semantic knowledge graph extraction
- MemOS & Memori: memory-as-infrastructure platforms for production agents
But there's no single hands-on guide that teaches you how each technique works, when to use it, and how to build it yourself.
That's why this repository exists. 30 techniques. Runnable notebooks. Real code you can use today.
🗺️ Taxonomy of Agent Memory Techniques
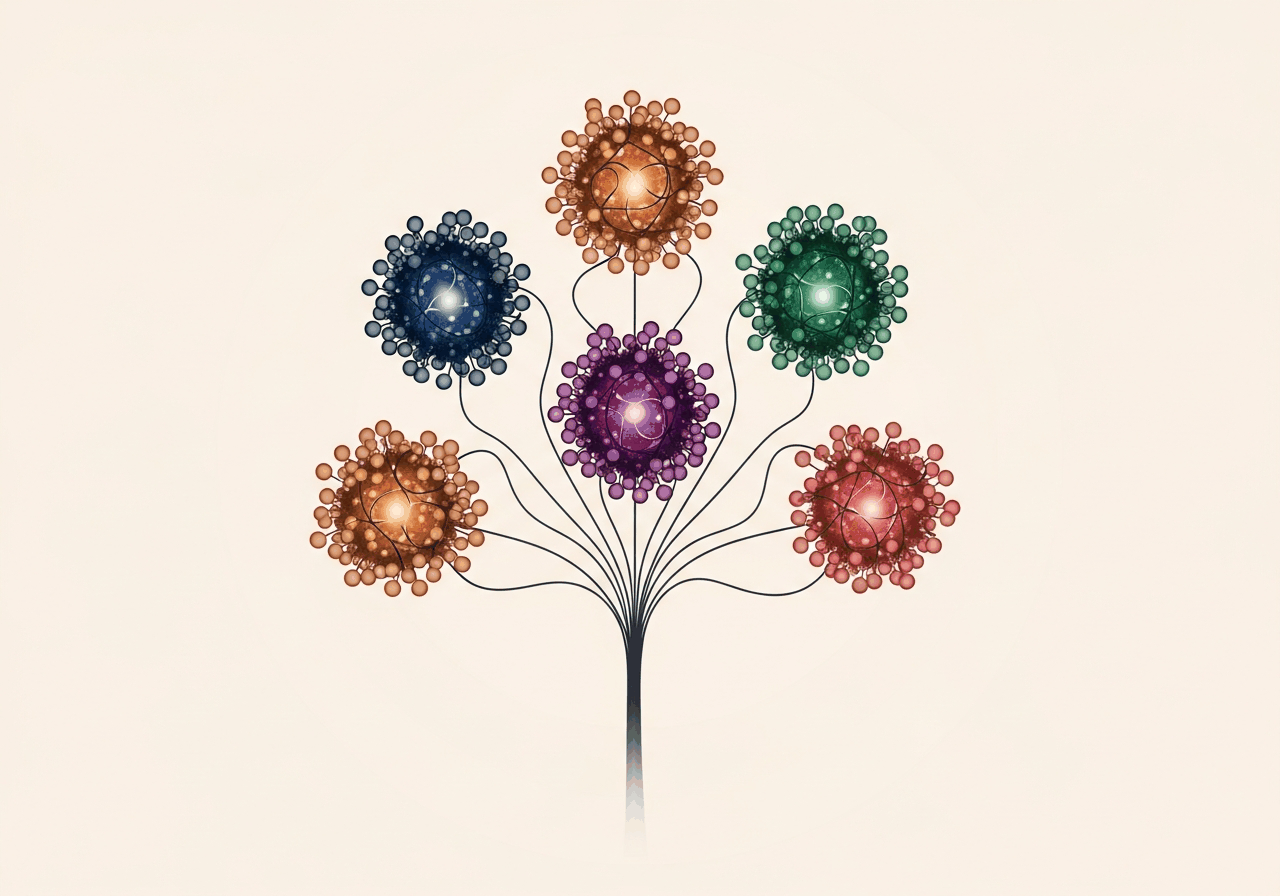
The 30 techniques fall into six families. Each family solves a different memory problem. Each technique lives in its own notebook.
| Family | What it solves | Techniques |
|---|---|---|
| Short-term | Keep recent turns in memory without filling up the context window. | 01 - 05 |
| Long-term | Save knowledge across sessions, users, and time. | 06 - 11 |
| Cognitive architectures | Working, hierarchical, and reflective memory systems. | 12 - 19 |
| Retrieval & routing | Choose what to recall and when. | 20 - 23 |
| Frameworks | Production-ready memory libraries (Mem0, Letta, Zep, Graphiti). | 24 - 27 |
| Evaluation & production | Measure, benchmark, and deploy memory. | 28 - 30 |
🧭 Which Technique Do I Need?
30 techniques grouped by what you are building. Pick the group that matches your goal, then open the technique inside it.
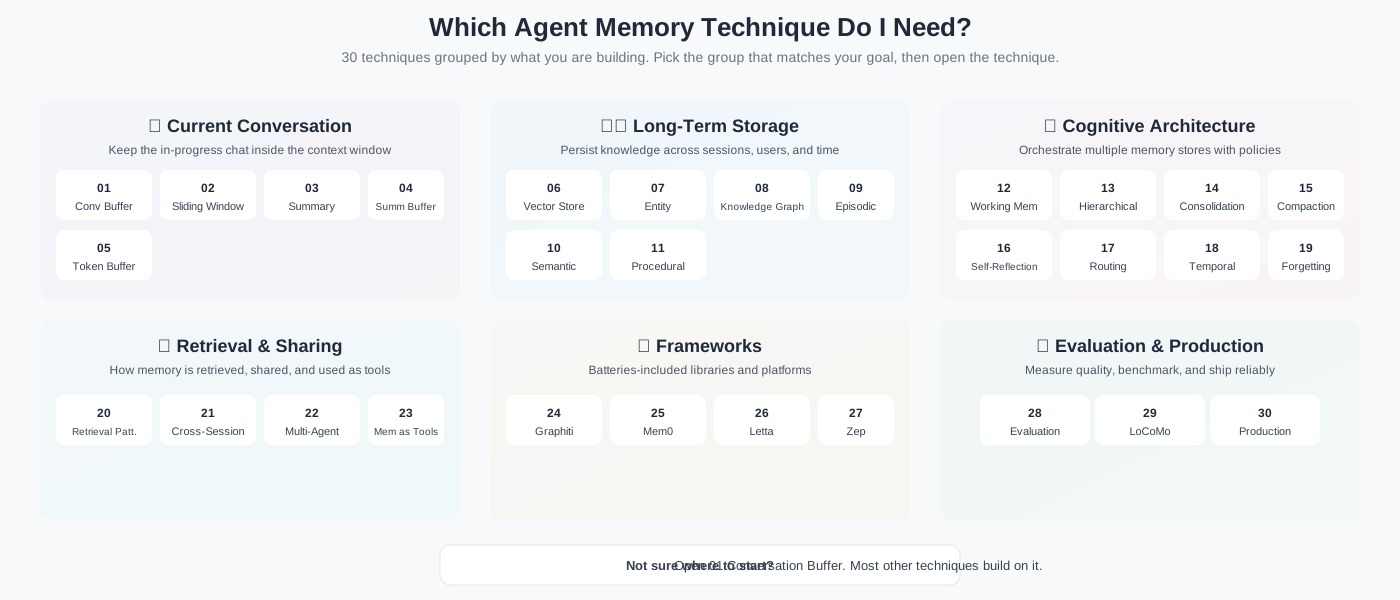
Quick text version:
- Need to manage the current chat? Start with 01-05 (short-term memory).
- Need to persist across sessions? Start with 06 Vector Store or 21 Cross-Session Memory.
- Building a cognitive architecture with multiple stores? See 12-19.
- Using a framework? Go straight to 24 Graphiti, 25 Mem0, 26 Letta, or 27 Zep.
- Evaluating or shipping to production? See 28-30.
Still not sure? Start with 01 Conversation Buffer. Almost every other technique builds on it.
📐 Compare Techniques at a Glance
Looking to filter by constraint (persistence, retrieval style, token cost, best-for use case)? See the side-by-side comparison matrix covering all 30 techniques in one table.
📚 All 30 Techniques
🔄 Short-Term Memory (Techniques 1-5)
Manage the conversation inside a single chat.
| # | Technique | Description | Notebook |
|---|---|---|---|
| 01 | Conversation Buffer Memory | Save the full conversation, word for word. The simplest pattern, and the base for everything else. | ✅ Notebook ·  |
| 02 | Sliding Window Memory | Keep only the last few messages. You limit the size, but you keep the recent parts. | ✅ Notebook · |
| 03 | Summary Memory | Replace old turns with a short summary written by the model. You lose length but keep the meaning. | ✅ Notebook · |
| 04 | Summary Buffer Memory | Summarize older turns, but keep recent messages word for word. You get both. | ✅ Notebook · |
| 05 | Token Buffer Memory | Trim the history to fit a strict token budget. Drop the oldest messages first. | ✅ Notebook · |
💾 Long-Term Memory (Techniques 6-11)
Storage that survives across sessions and users.
| # | Technique | Description | Notebook |
|---|---|---|---|
| 06 | Vector Store Memory | Turn past messages into vectors (number lists that capture meaning). Search them later by similarity. | ✅ Notebook · |
| 07 | Entity Memory | Pull out and track facts about people, projects, and preferences. Update them as the conversation grows. | ✅ Notebook · |
| 08 | Knowledge Graph Memory | Build a graph of how entities connect. Walk the graph to reason over what the agent has learned. | ✅ Notebook · |
| 09 | Episodic Memory | Store complete interactions with when-and-where context. Good for "what happened when" questions. | ✅ Notebook · |
| 10 | Semantic Memory | Pull general facts out of interactions. Store them on their own, away from the raw episodes. | ✅ Notebook · |
| 11 | Procedural Memory | Capture "how-to" knowledge: the procedures and workflows the agent picks up over time. | ✅ Notebook · |
🧩 Cognitive Architectures (Techniques 12-19)
Patterns borrowed from how humans remember.
| # | Technique | Description | Notebook |
|---|---|---|---|
| 12 | Working Memory & Context Window | Manage the agent's limited attention. Prioritize, pin, and evict context on the fly. | ✅ Notebook · |
| 13 | Hierarchical Memory Layers | Tiered storage with hot, warm, and cold layers. Promote and demote items as they age. | ✅ Notebook · |
| 14 | Memory Consolidation | Merge, deduplicate, and strengthen memories. Inspired by how the brain consolidates during sleep. | ✅ Notebook · |
| 15 | Memory Compaction | Compress stored memories with summaries, entity extraction, or distillation. Save storage and tokens. | ✅ Notebook · |
| 16 | Self-Reflection Memory | The agent looks back at its own actions. It writes notes on what worked, and uses them next time. | ✅ Notebook · |
| 17 | Memory Routing | Pick the right memory store to read from or write to. Route by content type and intent. | ✅ Notebook · |
| 18 | Temporal Memory | Attach timestamps to memories. Retrieve with time awareness and weight recent items higher. | ✅ Notebook · |
| 19 | Forgetting & Decay | Forget on purpose. Use decay, access counts, or relevance to prune. | ✅ Notebook · |
🔍 Retrieval & Multi-Agent (Techniques 20-23)
How agents find and share memories.
| # | Technique | Description | Notebook |
|---|---|---|---|
| 20 | Memory Retrieval Patterns | Compare retrieval strategies: semantic search, recency, hybrid scoring, diversity, and re-ranking. | ✅ Notebook · |
| 21 | Cross-Session Memory | Save and reload agent state across sessions. The user picks up where they left off. | ✅ Notebook · |
| 22 | Multi-Agent Shared Memory | Shared stores, message passing, and agreement protocols for multi-agent teams. | ✅ Notebook · |
| 23 | Memory with Tools | Give the agent memory tools it can call: save, search, forget. Treated like any other tool. | ✅ Notebook · |
🔧 Frameworks & Platforms (Techniques 24-27)
Work with the leading memory frameworks, hands-on.
| # | Technique | Description | Notebook |
|---|---|---|---|
| 24 | Graph Memory with Graphiti | Use Zep's Graphiti to build time-aware knowledge graphs from chat. Extract episodes and general facts. | ✅ Notebook · |
| 25 | Mem0 Patterns | Use Mem0's managed memory layer. It handles extracting, storing, and fetching user-specific memories. | ✅ Notebook · |
| 26 | Letta (MemGPT) Patterns | Build MemGPT's self-editing memory. Covers inner monologue, heartbeat events, and memory pressure. | ✅ Notebook · |
| 27 | Zep Memory | Use Zep for dialog classification, entity extraction, and time-aware graphs. Built for production. | ✅ Notebook · |
📊 Evaluation & Production (Techniques 28-30)
Measure your memory. Then ship it.
| # | Technique | Description | Notebook |
|---|---|---|---|
| 28 | Memory Evaluation | Measure memory quality. Check retrieval precision and recall, staleness, contradictions, and user satisfaction. | ✅ Notebook · |
| 29 | Memory Benchmarks (LoCoMo) | Run your memory against LoCoMo and LongMemEval benchmarks. See how it does over long conversations. | ✅ Notebook · |
| 30 | Production Memory Patterns | Run memory at scale. Caching, TTLs (time-to-live), sharding, backups, GDPR, and observability. | ✅ Notebook · |
🎯 Learning Paths
Beginner: Foundations
New to agent memory? Start here. These are the building blocks.
01 Conversation Buffer → 02 Sliding Window → 03 Summary Memory →
05 Token Buffer → 06 Vector Store Memory → 21 Cross-Session Memory
Intermediate: Structured Memory
Ready for more? Add entities, graphs, and smarter retrieval.
07 Entity Memory → 08 Knowledge Graph → 09 Episodic Memory →
10 Semantic Memory → 20 Retrieval Patterns → 22 Multi-Agent Shared Memory
Advanced: Cognitive Architectures
Build human-inspired memory patterns for advanced agents.
12 Working Memory → 13 Hierarchical Layers → 14 Consolidation →
16 Self-Reflection → 17 Memory Routing → 19 Forgetting & Decay
Practitioner: Frameworks & Production
Connect to production tools and measure what you've built.
25 Mem0 → 26 Letta/MemGPT → 24 Graphiti → 27 Zep →
28 Evaluation → 29 Benchmarks → 30 Production Patterns
🚀 Quick Start
💡 Prefer not to install anything? Every notebook renders on GitHub directly. Click a technique in the table above to read it in your browser. Or use the Colab badges to run it in the cloud.
# Clone the repository
git clone https://github.com/NirDiamant/Agent_Memory_Techniques.git
cd Agent_Memory_Techniques

# Create a virtual environment
python -m venv venv
source venv/bin/activate  # On Windows: venv\Scripts\activate

# Install dependencies
pip install -r requirements.txt

# Set up your API keys
cp .env.example .env
# Edit .env with your OPENAI_API_KEY and/or ANTHROPIC_API_KEY

# Launch Jupyter and start with the first technique
jupyter notebook all_techniques/01_conversation_buffer_memory/
📁 Project Structure
Agent_Memory_Techniques/
├── README.md                           # You are here
├── ROADMAP.md                          # Current state and what's next
├── LICENSE                             # Apache 2.0
├── CITATION.cff                        # How to cite this work
├── requirements.txt                    # Python dependencies
├── .env.example                        # API key template
├── llms.txt                            # LLM-discoverability index
│
├── all_techniques/                     # 30 technique folders, each with notebook + README
│   ├── 01_conversation_buffer_memory/
│   ├── 02_sliding_window_memory/
│   ├── ...
│   └── 30_production_memory_patterns/
│
├── docs/                               # Project documentation
│   ├── architecture.md                 # Memory system design patterns
│   ├── comparison.md                   # Side-by-side comparison of all 30 techniques
│   ├── glossary.md                     # Key terms and definitions
│   ├── learning_path.md                # Detailed learning path guide
│   ├── topics.md                       # Keyword index
│   ├── roadmap.md                      # Original planning archive
│   ├── FAQ.md                          # Frequently asked questions
│   └── CONTENT_STANDARDS.md            # Writing-style rules
│
├── .github/                            # GitHub community files
│   ├── CONTRIBUTING.md                 # How to contribute
│   ├── CODE_OF_CONDUCT.md              # Community guidelines
│   ├── SECURITY.md                     # Security policy
│   ├── FUNDING.yml                     # Sponsorship config
│   ├── ISSUE_TEMPLATE/                 # Issue templates
│   ├── pull_request_template.md        # PR template
│   └── workflows/                      # CI workflows
│
├── utils/                              # Shared helpers and validators
│   ├── helpers.py                      # Env loading, LLM clients, cosine, tokens
│   ├── validate_cells.py               # Notebook cell-structure validator
│   └── validate_style.py               # Prose-style validator
│
├── tests/                              # pytest smoke tests
├── data/                               # Small sample datasets
└── images/                             # Diagrams and visuals
📚 More from the same author
Run a course, newsletter, or dev community? You can earn 25% recommending RAG Made Simple to your audience.
🤝 Contributing
We welcome contributions. You can fill in a notebook, fix a bug, improve the docs, or propose a new technique. Every contribution helps the next reader.
See CONTRIBUTING.md for the details.
Where we need help the most:
- More techniques we haven't covered yet (propose one via an issue)
- Architecture diagrams (Mermaid or ASCII)
- More memory benchmarks and evaluation metrics
- Integration examples for new frameworks
💖 Sponsors
Supporting this project helps keep educational AI content free and open. If your company uses agent memory in production, consider sponsoring to get your logo below.
🔗 Related Work
This repo is part of a bigger collection of AI technique tutorials.
| Repository | Stars | Focus |
|---|---|---|
| RAG Techniques | 26k+ | Retrieval-Augmented Generation techniques |
| GenAI Agents | 21k+ | Generative AI agent architectures |
| Agents Towards Production | 18k+ | Production-grade agent deployment |
| Prompt Engineering | 7k+ | Prompt engineering techniques |
🏷️ Topics Covered
This repository is a practical reference for agent memory in Large Language Model (LLM) applications. For the full keyword index covering short-term, long-term, cognitive architectures, retrieval, frameworks, evaluation, and production patterns, see docs/topics.md.
⚠️ Disclaimer
This repository is for educational purposes. The code here shows how agent memory techniques work. It is not production-ready software. Do not use it as-is for handling regulated data, medical decisions, legal advice, or any high-stakes application without a careful review. The authors accept no responsibility for how you use this material.
📄 License
This project is licensed under the Apache License 2.0. See the LICENSE file for details.
📖 Citation
If you use this repository in your research or teaching, please cite:
@misc{diamant2026agentmemory,
    title={Agent Memory Techniques: A Cookbook for LLM Agent Memory},
    author={Nir Diamant},
    year={2026},
    url={https://github.com/NirDiamant/Agent_Memory_Techniques}
}
Built with care by Nir Diamant, making advanced AI accessible to everyone.